We're back with another weekly roundup, containing everything that we've published on Tom's Hardware Premium this past week. From a brand-new type of SSD to reasons why buying that expensive audiophile-grade headset might not be the wisest idea for gaming, and much more. To read any of the articles featured in this roundup, be sure to subscribe to unlock access.
TP-Link’s alleged ties to China have drawn scrutiny from regulators, even though the company says it split from its Chinese parent company back in 2024. With the FCC’s ban on foreign-made consumer routers in place, it has pledged nearly $1 billion in U.S. R&D and manufacturing, and has also signed a letter of intent with Key Tronic to assemble its Wi-Fi 8 routers in Mississippi, hoping to win approval. We chronicle the saga of keeping those routers off U.S. shelves, and how TP-Link hopes that Key Tronic will once again unlock the U.S. market for the networking firm.
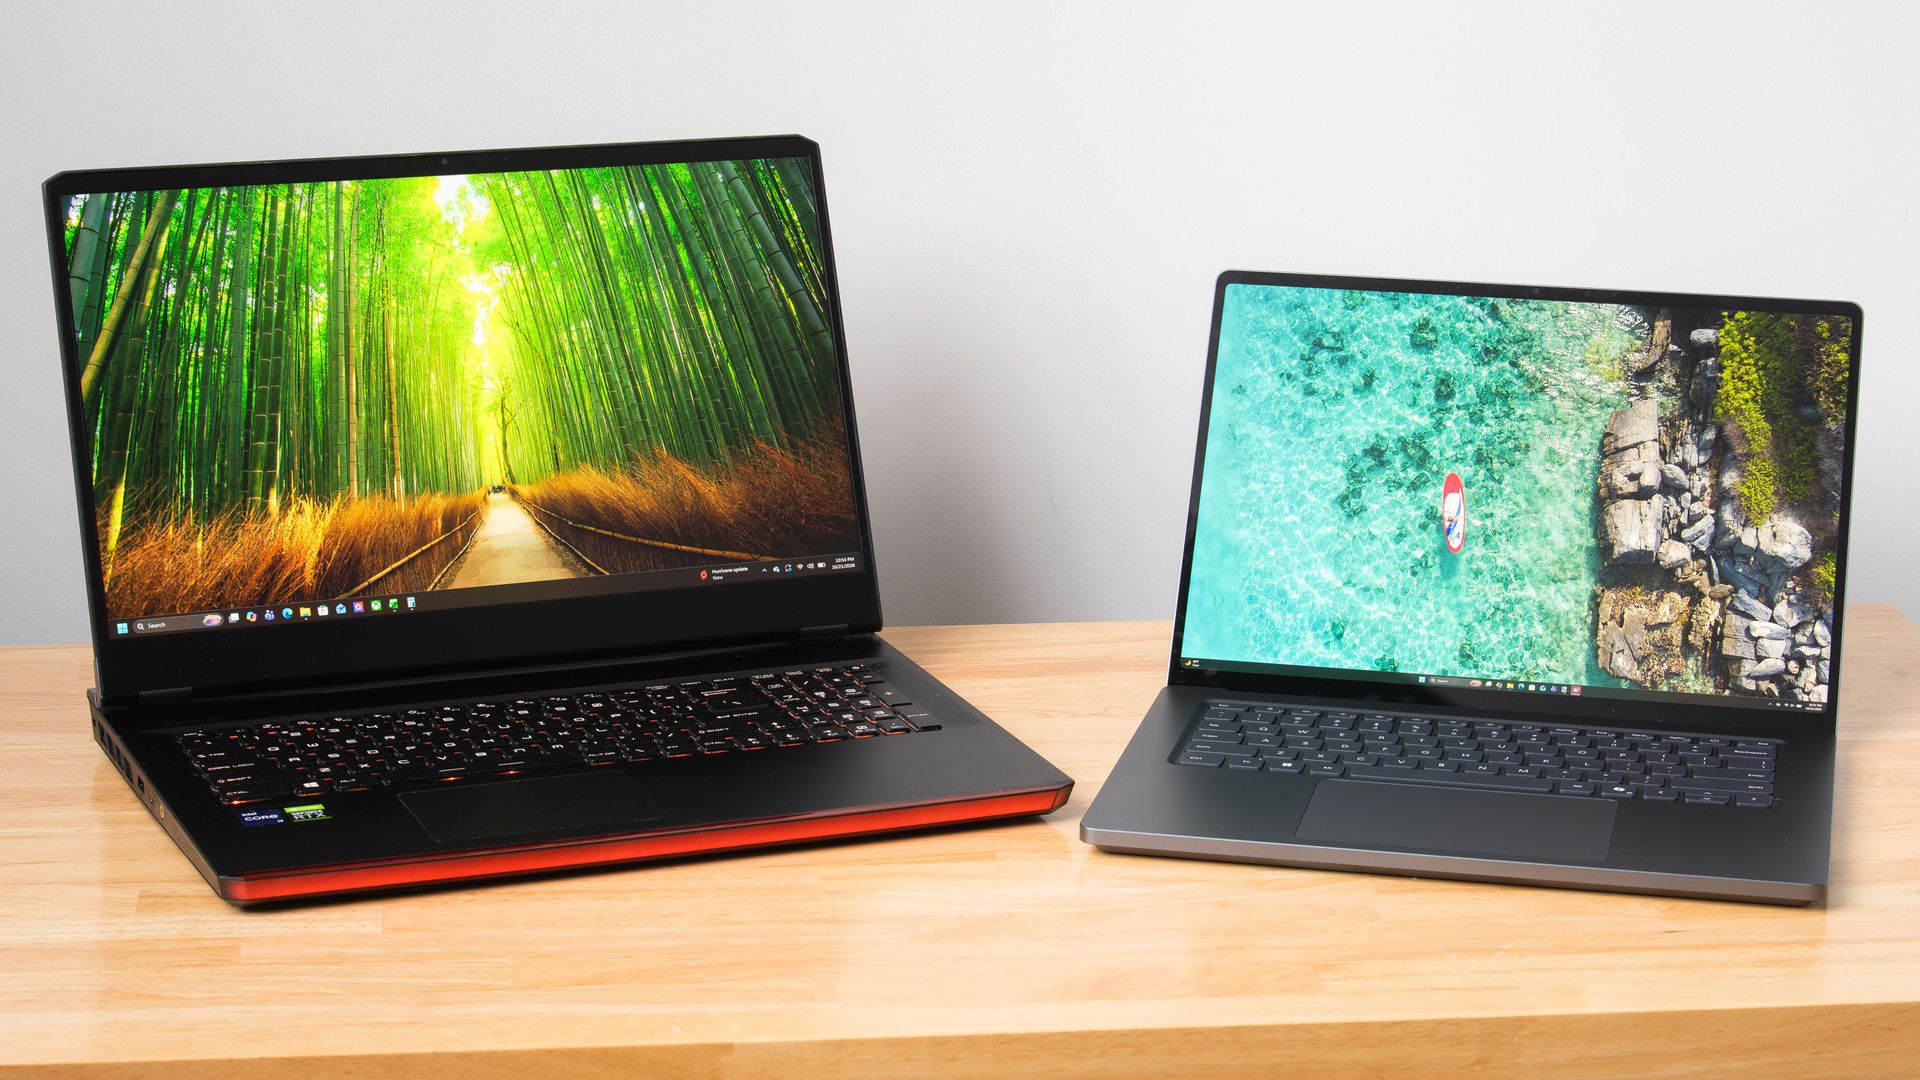
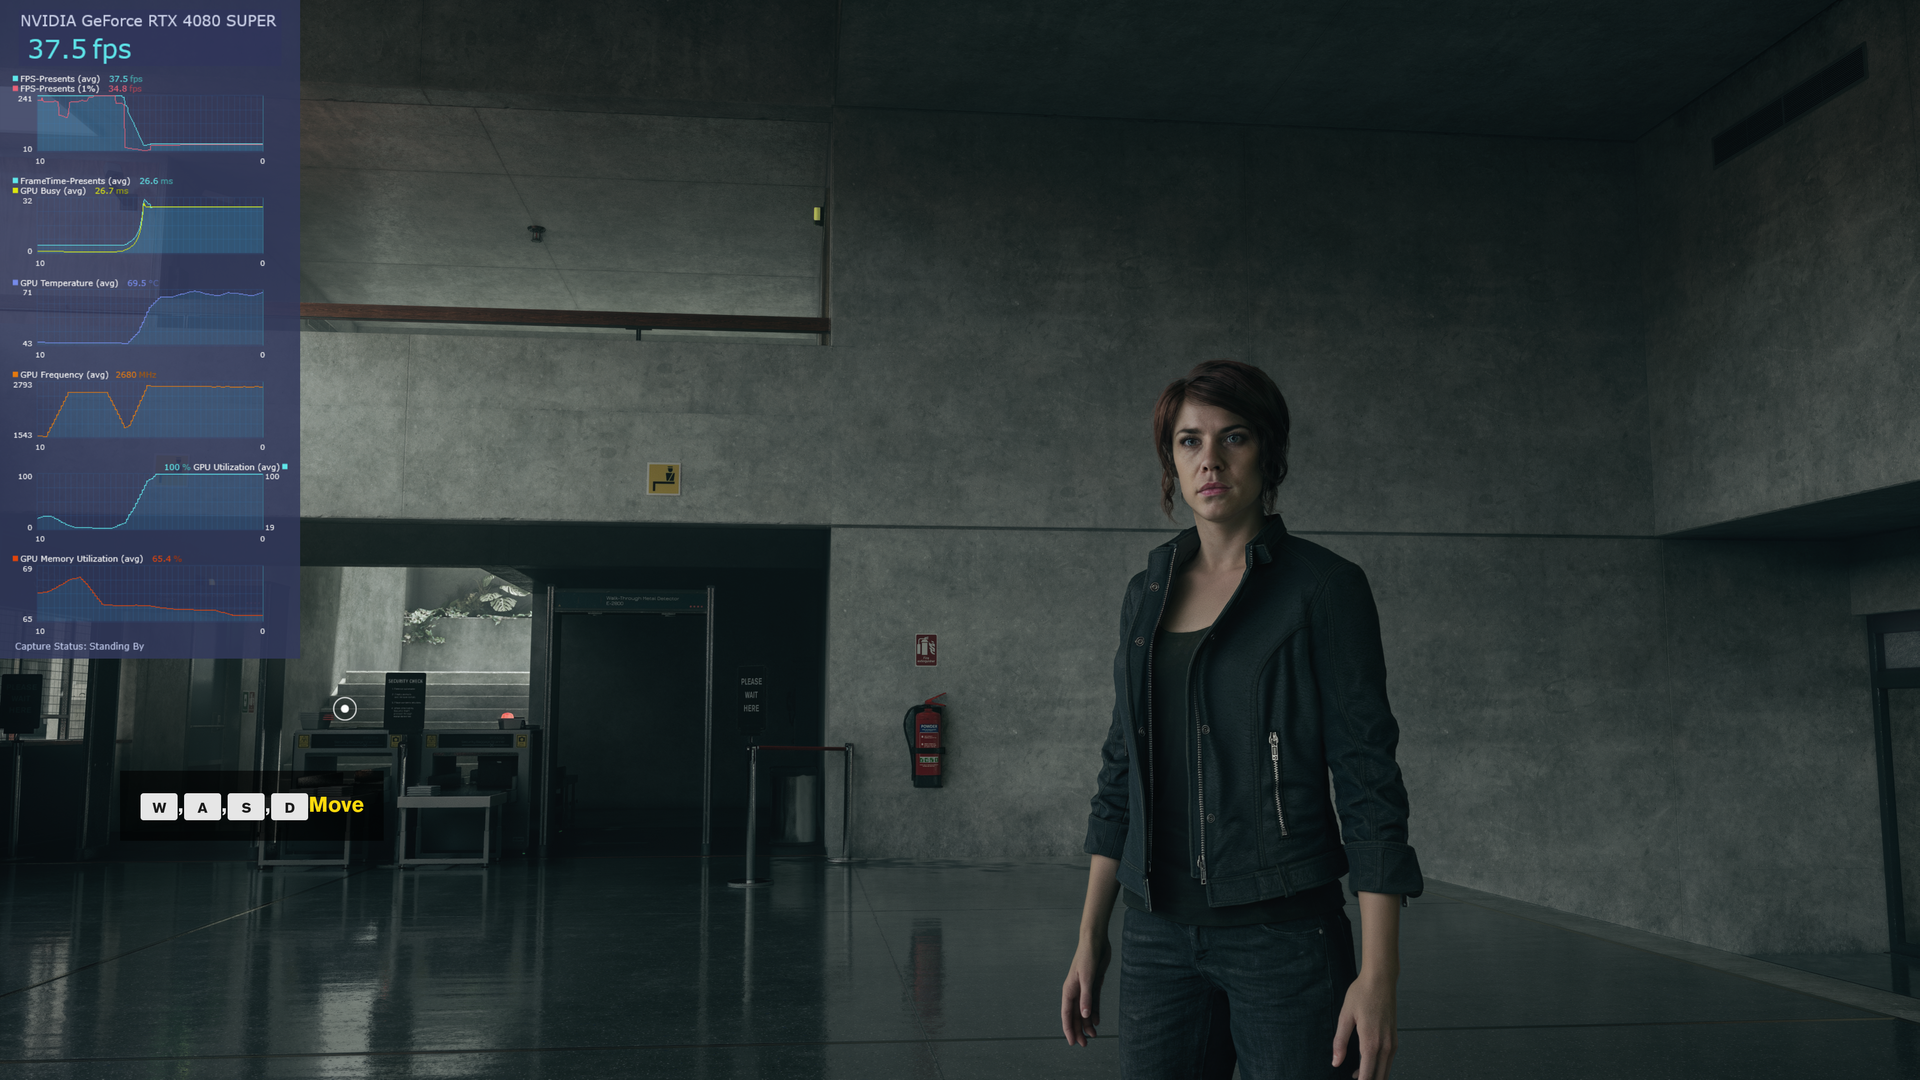
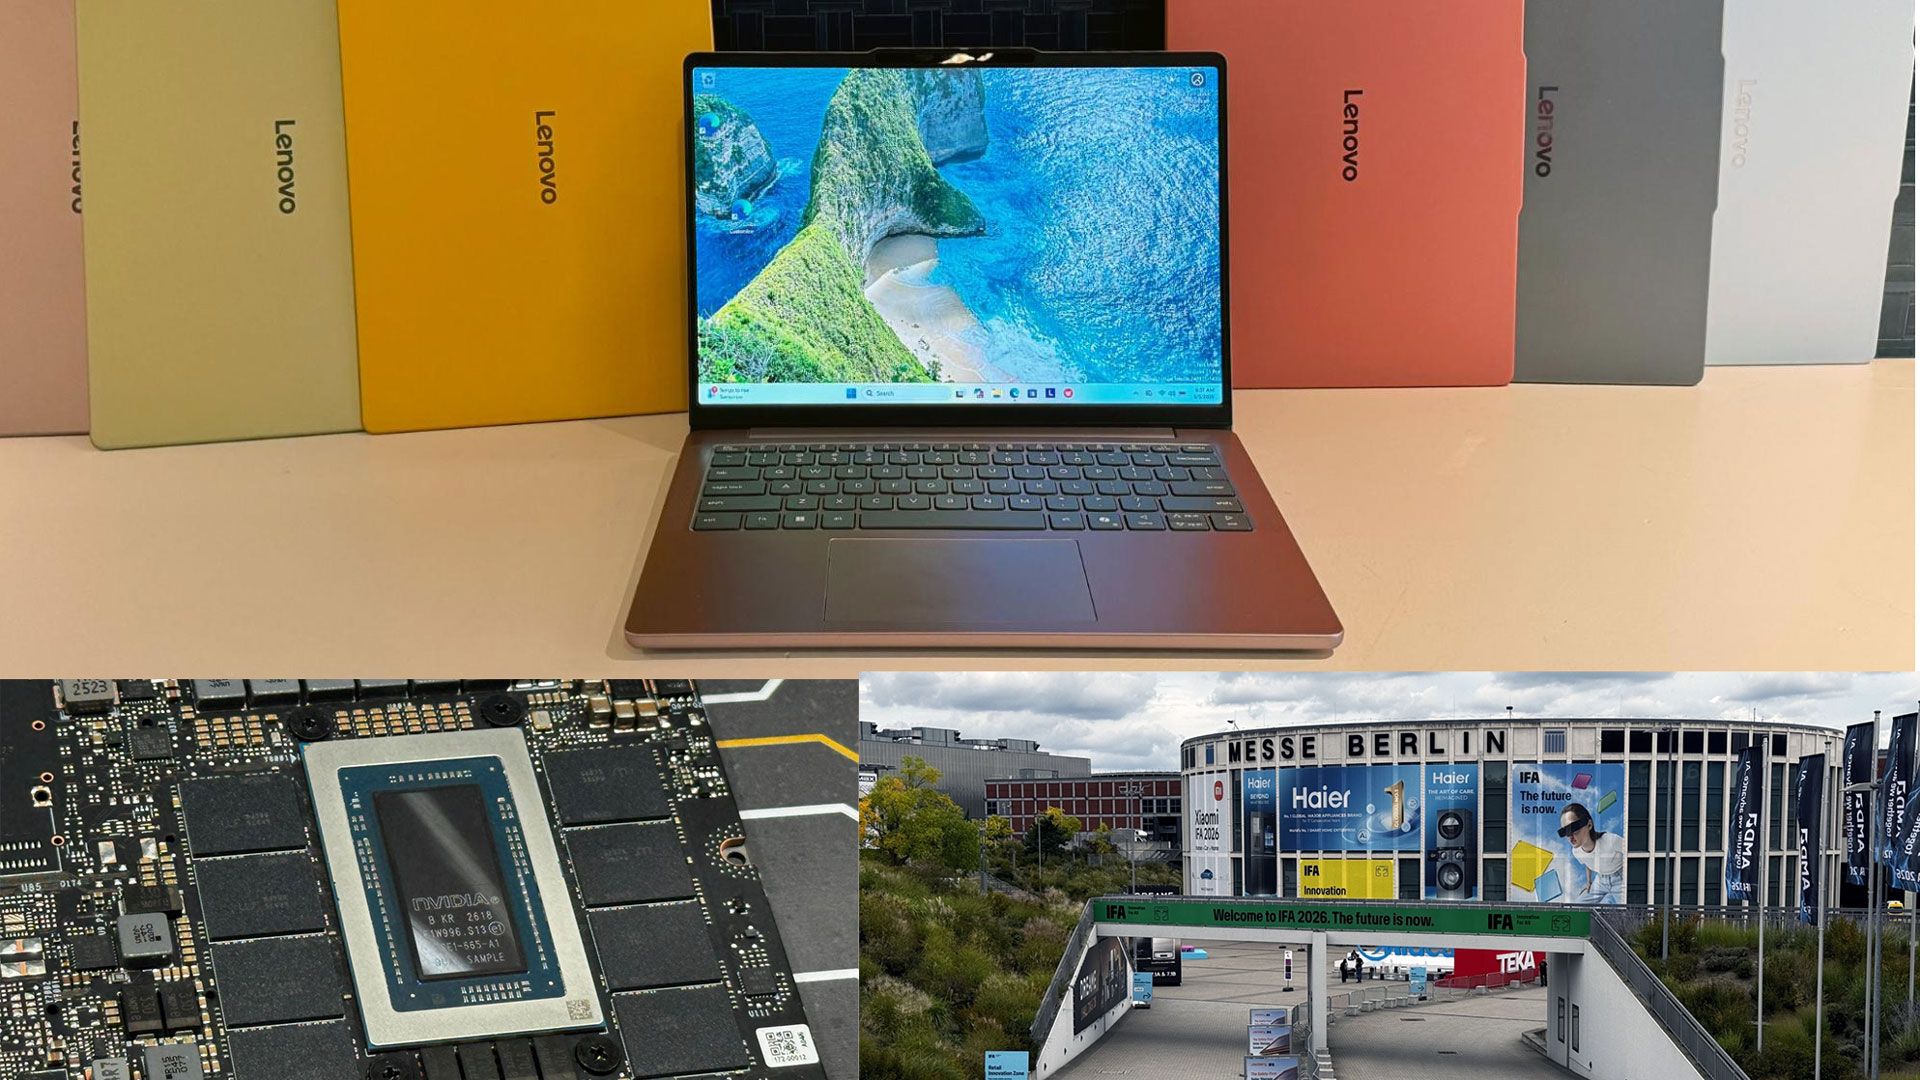
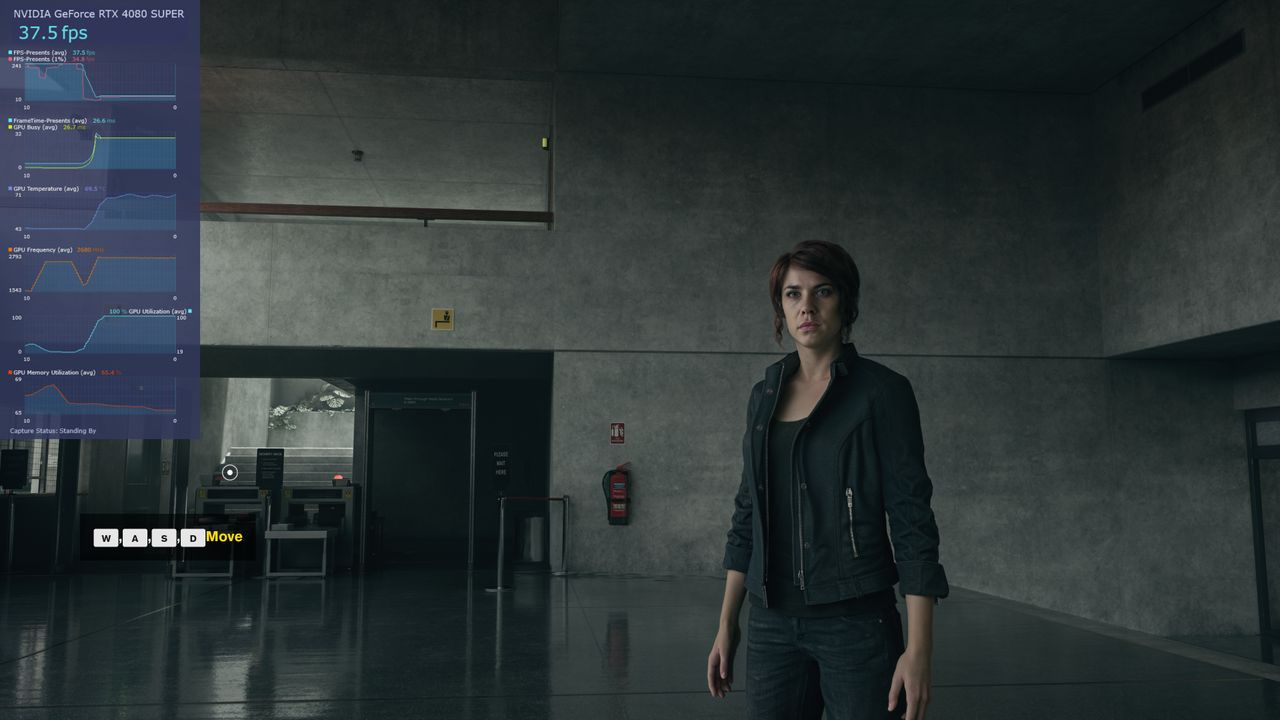
Last week saw the release of Nvidia's RTX Spark platform, with a brand-new high-end Microsoft Surface Laptop Ultra in tow. However, despite the device's focus on running local AI workloads and inference, it can be a capable gaming machine. There's just one thing getting in its way: a 3:2, 3270x2180 display that demands a lot out of the relatively humble Blackwell-based GPU within. We tested the ideal custom-resolution cocktails to bolster gaming performance on the Surface Laptop Ultra, with benchmarks on how it performs in Control Resonant, and how to get a better gaming experience out of Nvidia's pricey slab of silicon.
Gaming PCs and setups aren't merely about getting the best performance possible; it's also about immersion, comfort, and ease-of-use. All of those elements are heavily informed by your choice of gaming headset. With the market saturated up and down, ' audiophile'-grade headsets are sitting on storefronts with some of the heftiest price tags. So, is pure audio fidelity really the be-all and end-all for gaming headsets? We argue that other elements, like microphone quality and additional quality-of-life features, can make a bigger difference.
Tape storage is far from obsolete. As the AI boom produces and demands massive datasets that don't always need to remain on expensive SSDs or HDDs, tape shipments jumped by 57% year-on-year in Q1 2026. But where does the technology go next? We explore how companies like IBM, HPE, and Quantum are building new standards beyond LTO-10 with new standards and upcoming cartridges with up to 365TB native capacity, balancing time-tested reliability, performance and cost.
China's domestic chipmaking technologies have lagged behind Western counterparts due to a lack of access to advanced extreme ultraviolet lithography machines. However, despite this setback, the country continues to rely on older DUV machines instead. We talked to experts to find out how much further DUV can go.
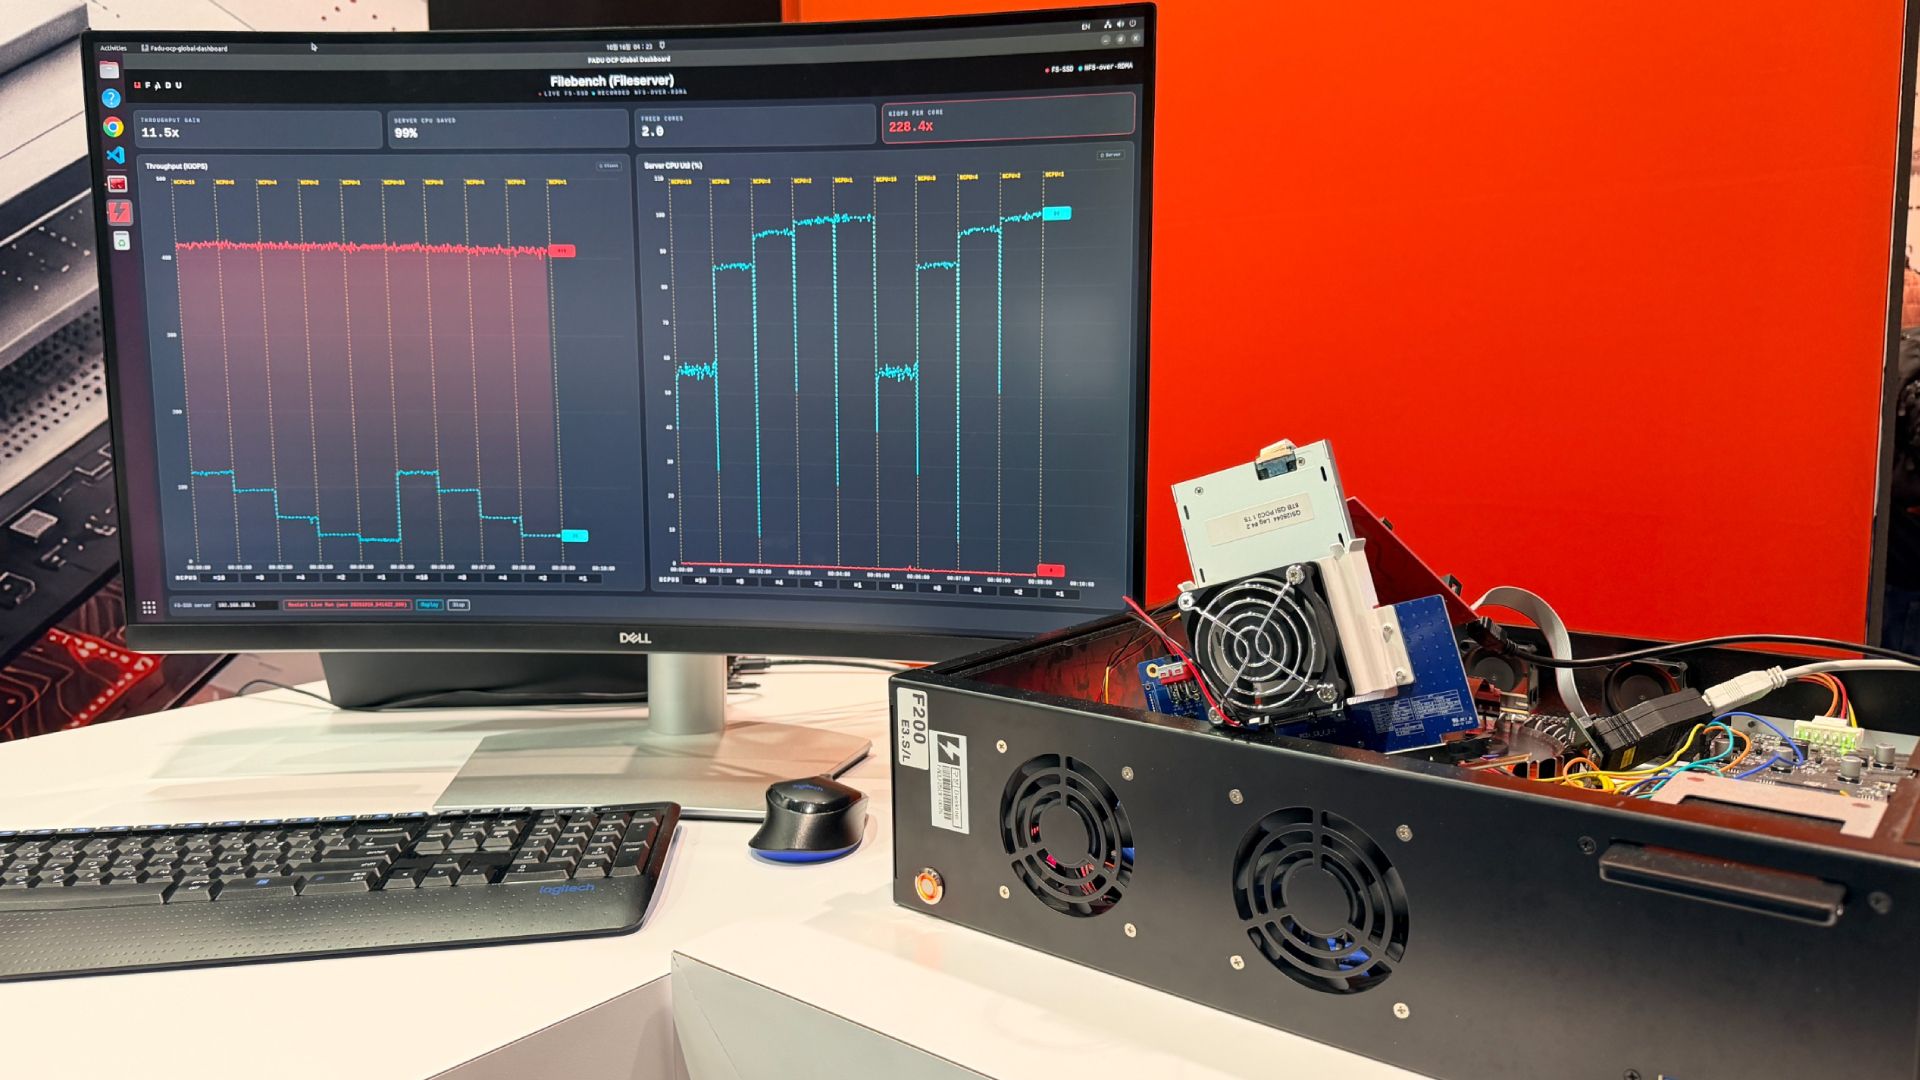
SSD controller designer FADU announced its File-Semantic SSD (FS-SSD) and detailed the technology in a white paper. The FS-SSD puts the filesystem directly onto the SSD's flash to bypass host CPUs, enabling GPUs, DPUs, and NICs to open and read files directly. The company also presented initial tests, with results that still need to be qualified by real silicon. The FS-SSD builds upon existing frameworks and a Gen6 controller, and the company claims that partner samples should be shipping by Q3 2027.
On the AI front, Deepseek released its latest AI model. Named Deepseek V4-Flash-1017, the model scores well across intelligence and agentic workloads broadly. However, further analysis of the open-weight model shows that it is more prone to hallucination than Western closed-source counterparts, which is important as the model sits directly between GPT 5.6-Sol and Claude Opus 5, but at a much lower cost-per-task ratio than either of the two, potentially making it an attractive option for those looking to run tasks with verifiable outputs like programming or OCR functions.
Vast swathes of modern tech infrastructure rest on open source software, yet many of the projects used by billions of people are either underfunded or understaffed. We explore a sobering report wherein 11 out of 23 critical pieces of open source infrastructure only have one or two maintainers. We look back at major vulnerabilities like Shellshock and Log4Shell to show what neglect can truly cost, and why the people maintaining these critical pieces of online infrastructure deserve more support.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
To read any of the articles we mention above, as well as unlock Bench, you'll need to purchase a Tom's Hardware Premium subscription. Your support goes a long way in helping us to publish deeper, more insightful articles that might not otherwise be covered.
This week, we've published a swath of news and features over on Tom's Hardware Premium. So, if you're not subscribed yet and wondering what you might be missing out on, we've got you covered. To read any of the articles listed here, be sure to arm yourself with a subscription to get access.
First up, we dug into Intel's EMIB and Foveros packaging roadmaps, as they continue to mature, and found new customers looking to cash in on building a more sophisticated offering. Intel's ultimate goal? To build system-in-packages the size of just 12 reticles using both EMIB and Foveros Direct 3D. We map out how the company plans to get there in our exhaustive report.
Over the past month or so, we saw the debut of DLSS 5 and Multi Frame Generation on older graphics cards. Both features are officially locked down to Blackwell-based GPUs only, but amidst spiraling prices and the curious disappearance of the RTX 5090 from store shelves, modders have taken it upon themselves to port these newer features to older GPU architectures. We had the opportunity to sit down with two such modders to learn more about how both Multi-Frame Generation and DLSS 5's neural rendering capabilities made it over to older GPUs.
Earlier, we alluded to the fact that new consumer PC hardware is becoming much more expensive to purchase when compared to just a few years ago. So, our resident deals guru, Stewart Bendle, took it upon himself to take a look at the market overall and discovered that, in all likelihood, you're not going to find the best deals on online storefronts. However, the best place to buy your new PC components is limited to whether or not you'll have a suitable brick-and-mortar Micro Center location near you. We pore over the bundles and deals that may make a trip more worthwhile than you might initially think.
While those articles clear things out for all of the features we've published on Tom's Hardware Premium this week, we've also got a slew of deep news analysis stories that subscribers can enjoy.
To start things off, ASML posted a record quarter this week, posting $13 billion in revenue, claiming that demand continues to outstrip its own supply when it comes to delivering its advanced lithography machines. The company is working on expanding supply, as demand continues to soar.
Googlebooks have officially landed. But where do they sit in the wider ecosystem of devices in 2026? And is it even a good idea to purchase one? With the premium offerings nearing MacBook Air territory, we muse on the awkward timing, spec choices, and pricing of Google's new class of device.
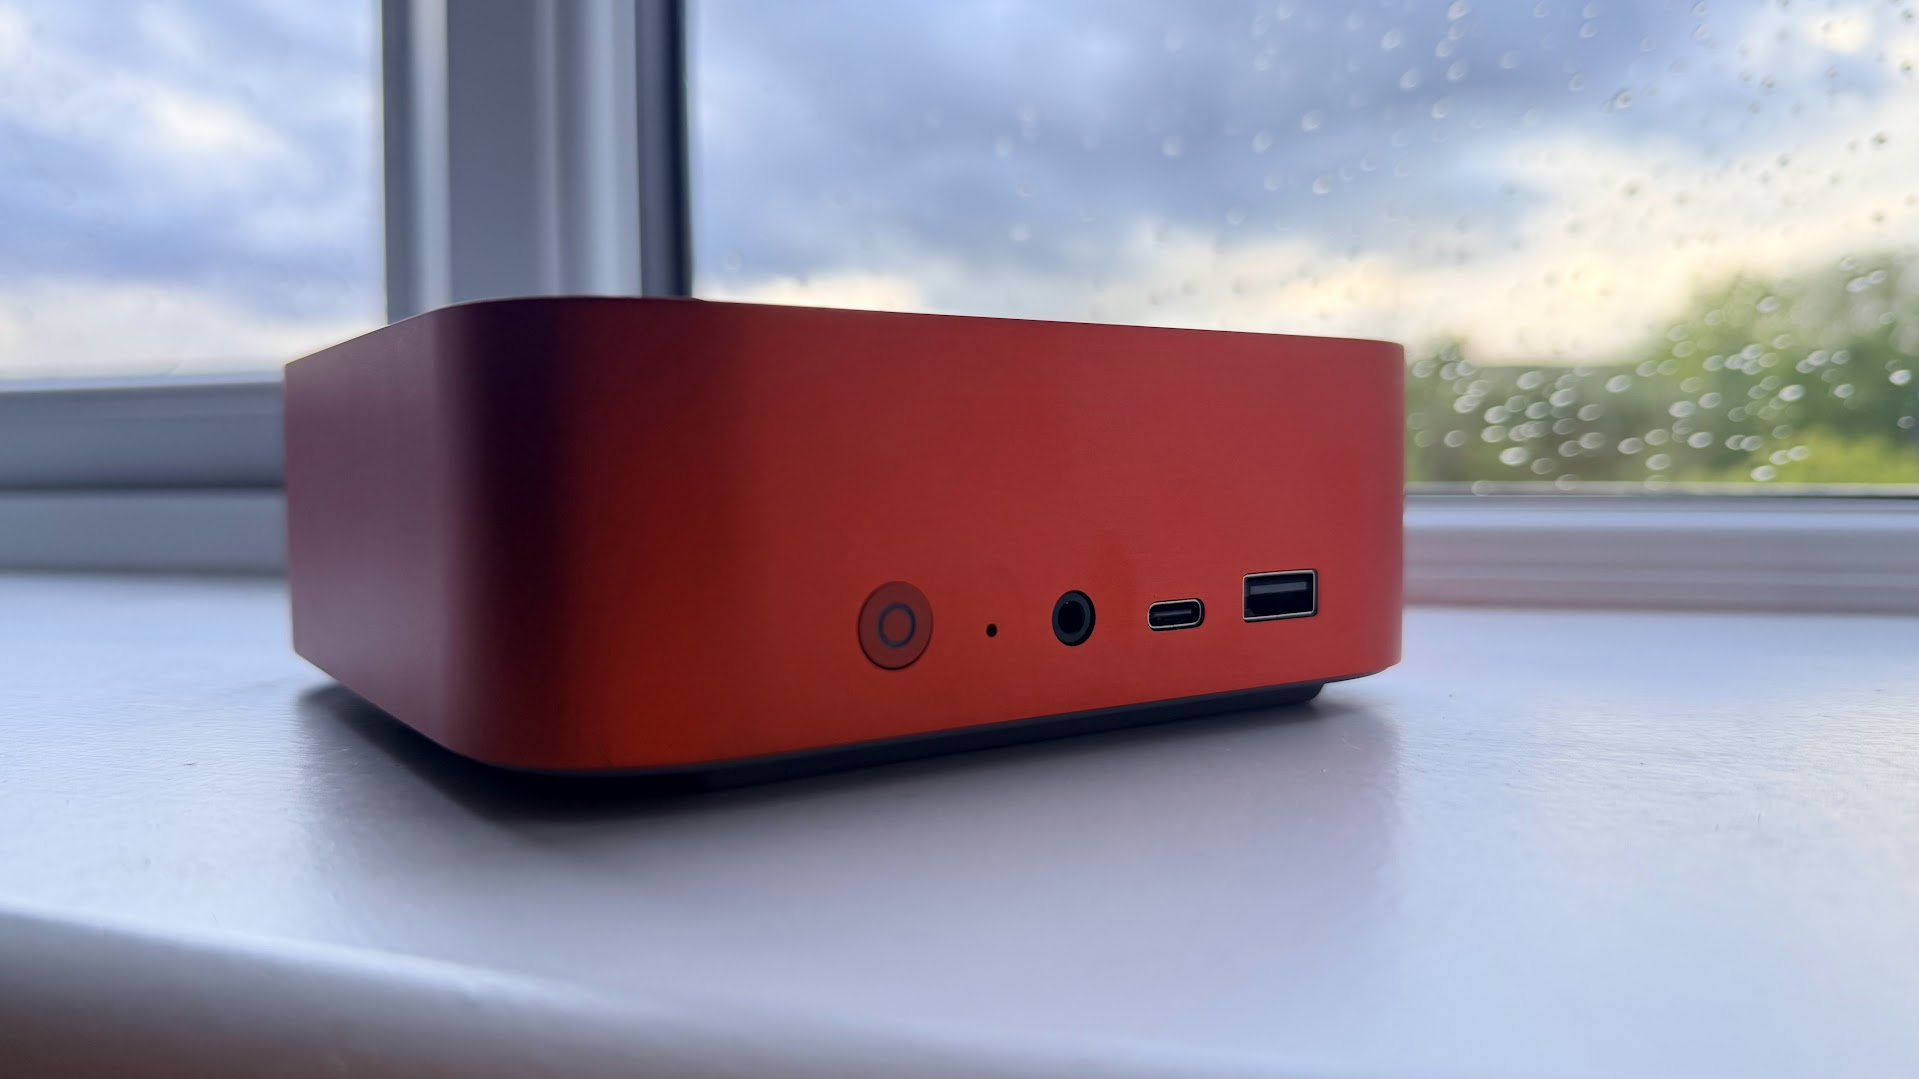
Speaking of new classes of device, the DGX Spark and Ryzen AI Halo platforms both take direct aim at local AI enthusiasts. But, since these devices have launched, prices have skyrocketed. Now, Sipeed is entering the arena with a competitor of its own. Named Maixstation, the device promises Spark-like performance, based on chinese silicon and 128GB of LPDDR5X at a much lower price than the current DGX Spark equivalent. We have all the details, including lofty performance claims, all of the specs, and much more.
SK hynix is reportedly set to place an in-house core, named a Hynix Transaction Processing Unit (H-TPU) in its SSD controllers to ease the load put on Arm cores. The benefits to using the new core, the company claims, is that they use less power, and free up the core Arm cores to work on other tasks, while the H-TPU works on repetitive operations.
Ukraine has targeted Russian Yandex data centers in the latest development in the conflict between the two nations in recent weeks. While bot traffic and online disinformation were distrupted, it also highlights just how fragile Russia's public services are, if data can simply evaporate due to less disaggregated infrastrucutre.
Of course, the world of AI continues to disrupt industries, and sometimes, itself. A few weeks ago we broke down TypeSafe's Jev, a decision model that spits out decisions based on the probability of its inputs. But, in the weeks following, companies have rushed to make its own decision models, and the provenance of the original idea of a decision model like Jev has been called into question.
Elsewhere, mathematicians are warning to not use AI when working and in research, as OpenAI posted 722 manuscripts and proofs in the field, which the community now has to qualify. This is an unprecendented event within the mathematics community, and the burden of non-artifically-generated proof lies in the research community itself.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
To gain full access to the articles we mention above, as well as unlock Bench, you'll need to purchase a Tom's Hardware Premium subscription. Your support goes a long way in helping us to publish deeper, more insightful articles that might not otherwise be covered.
Over recent weeks, we've seen the release of DLSS 5 Neural Rendering in NBA 2K27, followed by its porting to older GPU generations, and the unlocking of DLSS Multi Frame Generation (MFG) for older graphics cards. But how did all of that happen, and who are the people in the modding community unlocking features that Nvidia itself has locked off from users of anything but its latest Blackwell-based GPUs? We sit down with modders Dashdogy and Uncle Burrito to understand how, and why, the modding community has been breaking down Nvidia's software-based locks.
In 2025, during the release of the RTX 5000 series graphics cards, one Australian student was watching a Digital Foundry interview with Nvidia engineers, where the team was showing off Multi Frame Generation (MFG), a feature locked to Blackwell GPUs. During the podcast, the idea of MFG running on older RTX 4000 series hardware was floated, but the feature was never released for Ada Lovelace hardware. “Every few months, I would do a Google search to see if it ever happened or not,” said Dashdogy, a Physics Major studying Mathematics and Space Science.
“A few weeks ago now, the perfect storm arrived. Mid-semester break had just started, and I did the same Google search as I always do. But thought, maybe I’ll look into it. How hard could it be?”
One AWS instance, and a week of late nights later, he unlocked “true” MFG on Ada Lovelace hardware, a feat previously believed to be impossible due to incompatible instructions and a black screen that blocked the progress of modders before them. We’ve tested the mod extensively, and the results stand out. Multi Frame Generation has unofficially arrived for non-Blackwell hardware.
Dashdogy isn’t the only modder that’s been hard at work unlocking features for older-gen GPUs. Several weeks ago, when DLSS5’s Neural Rendering DLL first found its way onto the internet, RTX Remix modder Uncle Burrito set their sights directly on it. “I had no idea of telling [if running DLSS 5 on Ada] was even possible,” they said. Given the previous performance claims of requiring multiple RTX 5090s to run on its initial reveal, Uncle Burrito knew DLSS 5 would be computationally expensive, but that didn’t stop him from trying to get into the DLL itself.
“Once I reverse-engineered it, with the help of Claude, it became obvious that this was possible on Ada. Not only was most of the code compatible, but to me, it looks like Ada support was simply left behind as a work in progress, not as a hard limit.”
And so, less than a day after the DLL had been released in an early access version of NBA 2K27, Uncle Burrito had successfully ported the technology to Ada hardware. In the weeks since the release of Uncle Burrito’s initial unlock for DLSS 5 NR on Ada GPUs, Nvidia has clarified that Neural Rendering would indeed be supported by RTX 4000 series GPUs, lending credence to the idea that implementation on Ada GPUs was merely unfinished in the initial shipping versions of the DLSS 5 DLL.
These two foundational mods by Dashdogy and Uncle Burrito now serve as the baseline for endless numbers of forks and integrations of both Neural Rendering and MFG for older hardware, which have now allowed for ports all the way back to 2018’s Turing architecture, and in DLSS 5 NR’s case, ports to AMD hardware. It’s now as simple as using one of many tools to click-and-install both into hundreds of games.
Unlocking MFG (Dashdogy)
(Image credit: Nvidia)
Dashdogy’s experience in modding spans years, having created Stellaris mods while still in High School, making compatibility scripts to patch multiple mods together. But porting DLSS MFG to Ada devices was a different beast entirely. Blackwell and Ada use entirely different ISAs, despite their software similarities. “When this [running Blackwell instructions on Ada] happens, the frames will generate, but the GPU graphs an error and returns a black screen,” he explains.
Underpinning Nvidia’s implementations of DLSS in shipping titles are two pieces of software: a package named Streamline, which usually includes a suite of DLSS software, and is a universal translator that allows games to run various upscaling technologies like DLSS. Used in tandem with Streamline is a Neural Graphics Framework (NGX), Nvidia’s proprietary software that underpins its AI-powered efforts like Super Resolution and Frame Generation. As a game calls for tools, NGX cooks the computation, and Streamline serves them to a given game’s engine.
As Dashdogy explored how to make MFG compatible with Ada, the modder targeted Streamline and NGX directly. “I specifically spoof the Streamline and NGX calls in memory that define how many frames the GPU is allowed to generate.” This approach allowed an Ada-based GPU to think it was allowed to generate more frames than it ordinarily would. “It’s a pretty simple interception, and on 40-series turns 1 into a 5. Now the GPU knows ‘I am a 4080 and I’m allowed to generate five frames,'" which successfully swerved the black frame issue that other earlier modders encountered, thereby unlocking higher frame generation multipliers.
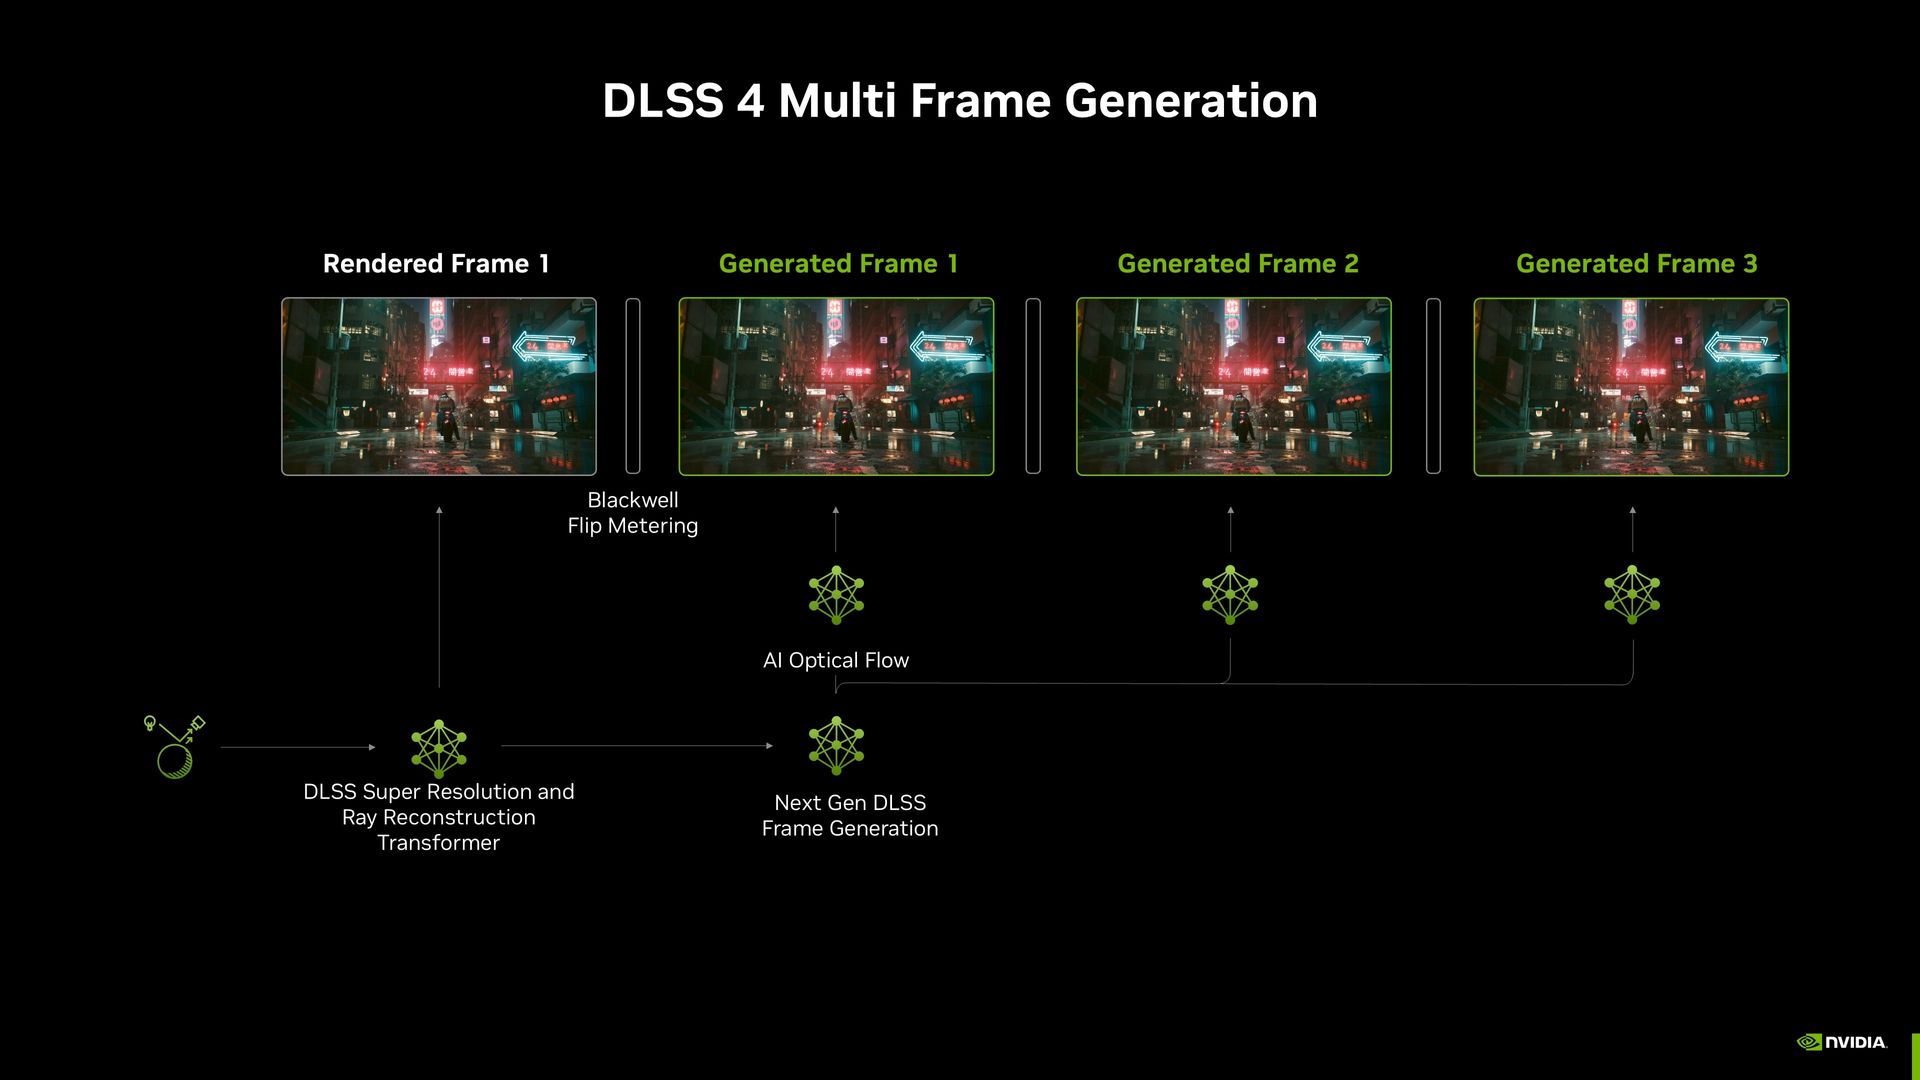
Dashdogy quickly packaged things up as a Cyberpunk 2077 mod, and shipped it off to Nexus Mods. This was the canary in the coal mine for a more mature integration, but things weren’t quite perfect yet. Dashdogy and other modders reported a problem — when using anything more than 2X MFG in Cyberpunk 2077 on Ada, things felt sluggish. Latency wasn’t great, and with the help of another modder, they believed that this was the work of the fabled “Hardware Flip Metering,” which smooths out MFG's outputs, and is a primary reason Nvidia offers as the reason the feature doesn’t work on older graphics cards.
Armed with a cloud instance that uses an RTX 6000 Pro Blackwell GPU, Dashdogy quickly went to work improving the MFG mod. “I conducted a kernel dump whilst the GPU was running MFG.” Dashdogy was also equipped with OpenAI’s Daybreak Blue AI model, a modified version of GPT 5.6-Sol with safeguards adjusted to allow for defensive cybersecurity tasks and vulnerability discovery. Using the model and his know-how, he analyzed the RTX 6000 Pro’s kernel dump to check where things might be going wrong for his MFG mod, directly comparing it to his native RTX 4000 Series integration.
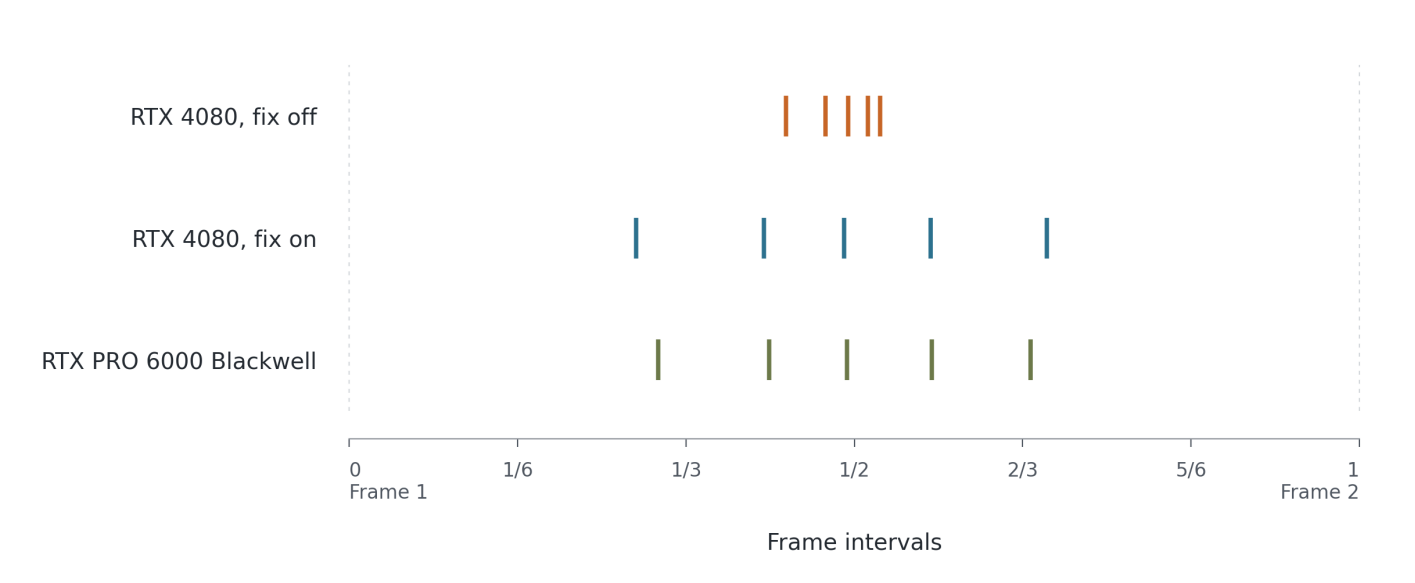
“For 6X frame generation, the GPU will render two real frames, then generate five frames and place them between those two real frames,” he told Tom’s Hardware Premium. Without copying this integration, frame pacing in his existing solution felt odd and disjointed.
"RTX 4080, fix off" shows us a cluster of frames with irregular pacing between raster frame intervals. (Image credit: Dashdogy)
“The 40-series-generated frames were all compacted around the middle of the two-frame interval. As you can see [in the image above], what we would expect, and what I measured from the [RTX Pro 6000 Blackwell], was five frames, neatly positioned at separate intervals. However, the 40-series GPU was forcing all of these around the same interval as 2X frame gen would put its one single frame.”
This caused the frame pacing of the MFG frames in the initial mod to feel sluggish, weird, and have poor responsiveness, as frame pacing is crucial in making a title feel smooth, especially when any frame generation tool is involved. “I discovered that the 40-series kernel responsible for motion processing was hardcoded to output a midpoint scaling for 2x only,” Dashdogy described. “With multiple generated frames, that compressed their represented motion toward the middle. With the fix, they spread out much more like the Blackwell reference.”
“The mod can work anywhere normal frame generation is implemented in any game,” Dashdogy told us, with additional telemetry for users to see exactly what’s changing. “The kernel is the same for both 40-series and 50-series; [it’s] just architecture-specific functionality [which blocks MFG on Ada]. 50-series has a number of Blackwell-specific optimizations that I’ve backported as well, and they contribute to better latency overall.”
The modder explains that the frame pacing fix was the most difficult part of the now-universal MFG port to Ada. But after its release, it now sits as a loadable ASI in a game’s directory and controls up to 6X frame generation in supported titles. The project has since been forked by other authors, which plugs the logic Dashdogy wrote into ReShade, a popular graphics mod tool.
Unlocking DLSS 5 NR (Uncle Burrito)
(Image credit: Remedy Entertainment / Tom's Hardware)
“I’ve been working with 3D art and graphics for many years now,” explains Uncle Burrito, a graphics enthusiast who implemented Path Tracing into Need For Speed Underground 2 using RTX Remix several years ago. “Over the years, I’ve stayed in the RTX Remix community to learn a lot more about real-time rendering and the techniques used for it.”
After hanging out in Nvidia’s RTX Remix Discord channel, news of the emergence of DLSS 5’s nvngX_dlssnr.dll spread like wildfire. According to Uncle Burrito, mods quickly clamped down on discussion of the DLL, and modders flocked to private channels and alternative servers, such as the RenoDX Discord server, to discuss development and integration. The DLL itself was written specifically for Blackwell, but the Ada architecture shares the ability to read FP8 instructions, which is what the DLL uses to load DLSS 5 Neural Rendering’s model weights.
Using that as a starting point, Uncle Burrito quickly went to work. “The model itself is just weights. These weights need code to be executed. The code was only written for Blackwell. CUDA binaries, right?” he explained. But despite this, and the aforementioned difference in ISAs between Blackwell and Ada, certain instructions could not be read by the humbler RTX 4000 series GPUs.
“Four of the 15 CUDA binaries [contained within nvngx_dlssnr.dll] would not run on Ada.” But this wasn’t an impossible task, as Uncle Burrito previously explained. The integration for Ada appeared unfinished and therefore, not entirely impossible. “I simply needed to patch the replacement compiled binaries”, meaning that it only took patching four affected CUDA binaries to get things up and running for RTX 4000 series graphics cards, Uncle Burrito told Tom’s Hardware Premium.
Uncle Burrito, alongside Ghidra, a reverse engineering tool, and an instance of Claude Code, set out to recompile the incompatible binaries to design a patch, but fell into a roadblock made by Claude itself. “I’m not too familiar with reverse engineering myself [...] Claude made the decision to use the incorrect version of the CUDA SDK to compile the replacement [binaries].” And so, the patched DLL ran, but instead output a black screen. “I could see the NR debug banner, and it did affect my framerate, but the output was completely black.”
“This is one of the many pitfalls of vibe coding,” Uncle Burrito said. “You can’t make anything good if you don’t understand what you’re working on. Usually, I don’t give the model any room to gaslight or make a wrong decision. If you don’t know what you’re doing, then don’t expect miracles.”
After realizing the mistake and recompiling with the correct CUDA SDK, the results were quickly posted to the RenoDX Discord server. “Ada performance is about as good as it can get. It has native FP8 support, so the hardware is doing its best. The rest can be attributed to simply not [having] enough horsepower in the chips.”
The simplicity of the patch might appear to be surprising, but the DLL leans on the same information that’s standardized between games and platforms, similar to how Streamline works in most game engines. “Motion vectors and depth buffer are [two] of the few things in graphics programming that we’ve standardized. Almost every modern game produces motion vectors, and rasterization isn’t possible without a depth/z buffer,” Uncle Burrito told us. Therefore, the DLL becomes a drop-in replacement for the officially distributed one, which unlocks the functionality on Ada.
Uncle Burrito’s methodologies were since picked up by RenoDX’s ShortFuse, who then worked on porting the DLSS 5 NR DLL to Ampere and Turing generation graphics cards. That porting work is more involved, since it also includes the translation of the model to be read by FP16 instructions. Following the release of Uncle Burrito’s work, a new DLL has emerged, with universal compatibility between Turing, Ampere, and Ada generations.
Unblocking the software lockouts
(Image credit: Nvidia)
Between the MFG unlocker from Dashdogy and the patched Neural Rendering DLL created by Uncle Burrito, the community-made mods both unlock functionality that would not have come to older-generation cards or would have otherwise been added at a later date. According to Dashdogy, “40-series has no excuse” when it comes to support for Multi Frame Generation. “It’s a very small change that allows [the mod] to work,” noting that additional work is being done to recompile things for Turing and Ampere, with the caveat that latency and overheads get higher the further you go back.
“It always comes down to performance,” Uncle Burrito said. “It’s fair for [Nvidia] to not include Ada until they can get the optimization part sorted.” The modder further adds that the situation can be read in both ways, as a method for Nvidia to sell more RTX 5000 series graphics cards, and to have more time to optimize Neural Rendering for older RTX 4000 series GPUs.
Everyone wants to make the most out of their available hardware, especially at a time when consumer graphics pricing has firmly rocketed past the moon, with RTX 5090 GPUs now approaching north of $9,000. “I personally think [the MFG mod] is really important in the current market,” Dashdogy adds. “... many are just getting priced out of the new generation entirely, so giving people the ability to hang on to their GPUs for a little bit longer is going to help a lot of people stay invigorated and connected to the hobby.”
If a single Australian student can unlock DLSS MFG for older GPUs, Nvidia’s claims of hardware exclusivity appear less like a technical limitation and more like artificial lockout. For those unafraid to modify a few simple files within a game, those features are all readily available, albeit unofficially. There’s an irony in how both MFG and Neural Rendering were ported to older GPUs — the development of both mods relied on cutting-edge AI models — powered by the same ecosystem that’s driving Nvidia’s earnings. Now, the very same AI revolution Nvidia champions is being used to tear down its own walled garden.
In case you've been missing out on the action over on Tom's Hardware Premium, we're back with another roundup to fill you in on everything you missed. Central to this week's theme is how Artificial Intelligence and its subsequent buildout are currently impacting all areas of the semiconductor industry.
Headlining this week is our report on how smart software utilization may play a part in the electricity consumption of AI data centers. We sat down and talked with experts in the domain to find out.
Reports state that Tencent has reached a deal to lease high-performance AI chips from Oracle to the tune of $7 billion over five years. While the figure on its surface sounds significant, the estimated lease price is around 43% less than an Nvidia H100 leased at $2.80 per hour on a one-year contract, meaning that Tencent may have scored a slight coup in the terms of its lease agreement. While no specific chips have been named, the size of the deal and the prices point toward a Hopper-class GPU. We explored how this rental loophole may be used by Chinese firms to potentially gain access to otherwise export-controlled hardware.
If you cast your minds back to last week, Synopsys revealed a slew of new agreements and partnerships; one of the most notable among them was an agreement with OpenAI, unveiling a 'GPT-Synopsys' — a specialized AI model that leverages Synopsys' domain IP knowledge and EDA tools, with OpenAI's capability to design LLMs. GPT-Synopsys is, in all likelihood, a chipmaking-specialized AI model, which may play a part in the development of successors to OpenAI's Jalapeño AI ASIC. As we've previously explored, AI models designing chips will likely run into hurdles surrounding IP usage, which become a non-factor if both AI labs and IP holders decide to team up in a manner such as this, setting the stage for chip design's agentic future.
Neon is a noble gas that's widely used in the DUV chipmaking process, with over 70% of global supply being used by the now-older lithography machines. Crude neon production has usually been focused in Ukraine, and ever since the advent of the country's ongoing conflict with Russia, global supply has been disrupted. Now, companies are racing to bring neon gas recycling systems to market in order to make the most of supplies. Japanese lithography toolmaker Gigaphoton and rival Kanten Techno have both developed machines that recycle the material at varying degrees of success. While DUV lithography remains a primary focus for the Chinese chipmaking ecosystem, the material is not widely used in the newer EUV systems that many leading-edge nodes currently utilize.
Qualcomm has reportedly reached a deal with Huawei to license its patents for the first time. While the official announcement is light on detail and subject to approval, an additional report claims that Huawei's LogicFolding chip-stacking methods are also included in the deal, with products ranging across AI, networking, compute, and other technologies. What makes Huawei's LogicFolding approach so notable is that the technique follows and targets faster data transmission as a foil to not having access to the most advanced EUV machines. Additionally, many of the techniques that LogicFolding incorporates echo what others in the chip industry are already doing, which makes it an eyebrow-raising move on Qualcomm's part. Historically, patent licensing between the two companies has been on the other foot — Huawei licensing Qualcomm patents — not the other way around. We explore the deal in detail in our full article.
Two former Groq employees and shareholders have filed a proposed class action lawsuit against Groq's former board and CEO, alleging that the company's board breached its duties and cost stockholders billions, following Groq's $20 billion deal with Nvidia in December 2025, according to a new report. The deal between Groq and Nvidia didn't involve an acquisition, and Nvidia is not a named defendant in the case, though the vast majority of Groq's staff have reportedly since joined Nvidia directly. The Groq3 LPU has since been showcased as a part of Nvidia's Vera Rubin ecosystem, which is currently ramping. Nvidia's Groq 3 LPX is scheduled to ship alongside Vera Rubin in H2 2026.
The AI train keeps rolling, with a new release from European firm Mistral, named Large 4, ML4, or, if you have seen any of the company's social media posts, Le Chonk. The race towards building capable open-weight models has predominantly been dominated by either U.S. or Chinese labs, meaning a European breakthrough is significant. Testing lab Artificial Analysis scored ML4 a reasonable 38 on its overall intelligence index, and it is currently outrun by numerous Chinese models, including Kimi K3 (max), GLM-5.3-Flash, and MiMo-V2.6.Pro. However, the model excels in cybersecurity tasks, only outmatched by a select few.
So, Europe's sovereign AI efforts appear to still be playing catch-up to Chinese alternatives, despite clear advancements. The global race to deploy capable closed and open-weight models marches on, and Mistral expects that the exact weights for ML4 will be released before the end of October.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
To gain full access to the articles we mention above, as well as unlock Bench, you'll need to purchase a Tom's Hardware Premium subscription. Your support goes a long way in helping us to publish deeper, more insightful articles that might not otherwise be covered.
Over at Tom's Hardware Premium, we've been publishing a slew of stories centered around our themed AI Chip Design Week, where you can learn more about how artificial intelligence is reshaping the chipmaking world. Each article in our series of stories is free to access for a limited time, and we're extending the free period over the weekend until Monday, October 5, so you don't miss out.
Headlining this week is our interview with OpenAI hardware VP Richard Ho, talking all things Jalapeño, the Broadcom co-developed inference ASIC that the company debuted earlier this year at Hot Chips 2026. The interview dives into how the company used AI within its design processes, beating Nvidia on efficiency, and demystifying common misconceptions like only being optimized to run OpenAI models. This lengthy read is a full, unredacted transcript of our session with Ho, so don't miss out.
But how close is AI to designing the very silicon that it runs on? We explore the concepts, products, and everything else shaping the industry in our pair of exhaustive primers on the subject, covering the companies seeking to make the chips themselves.
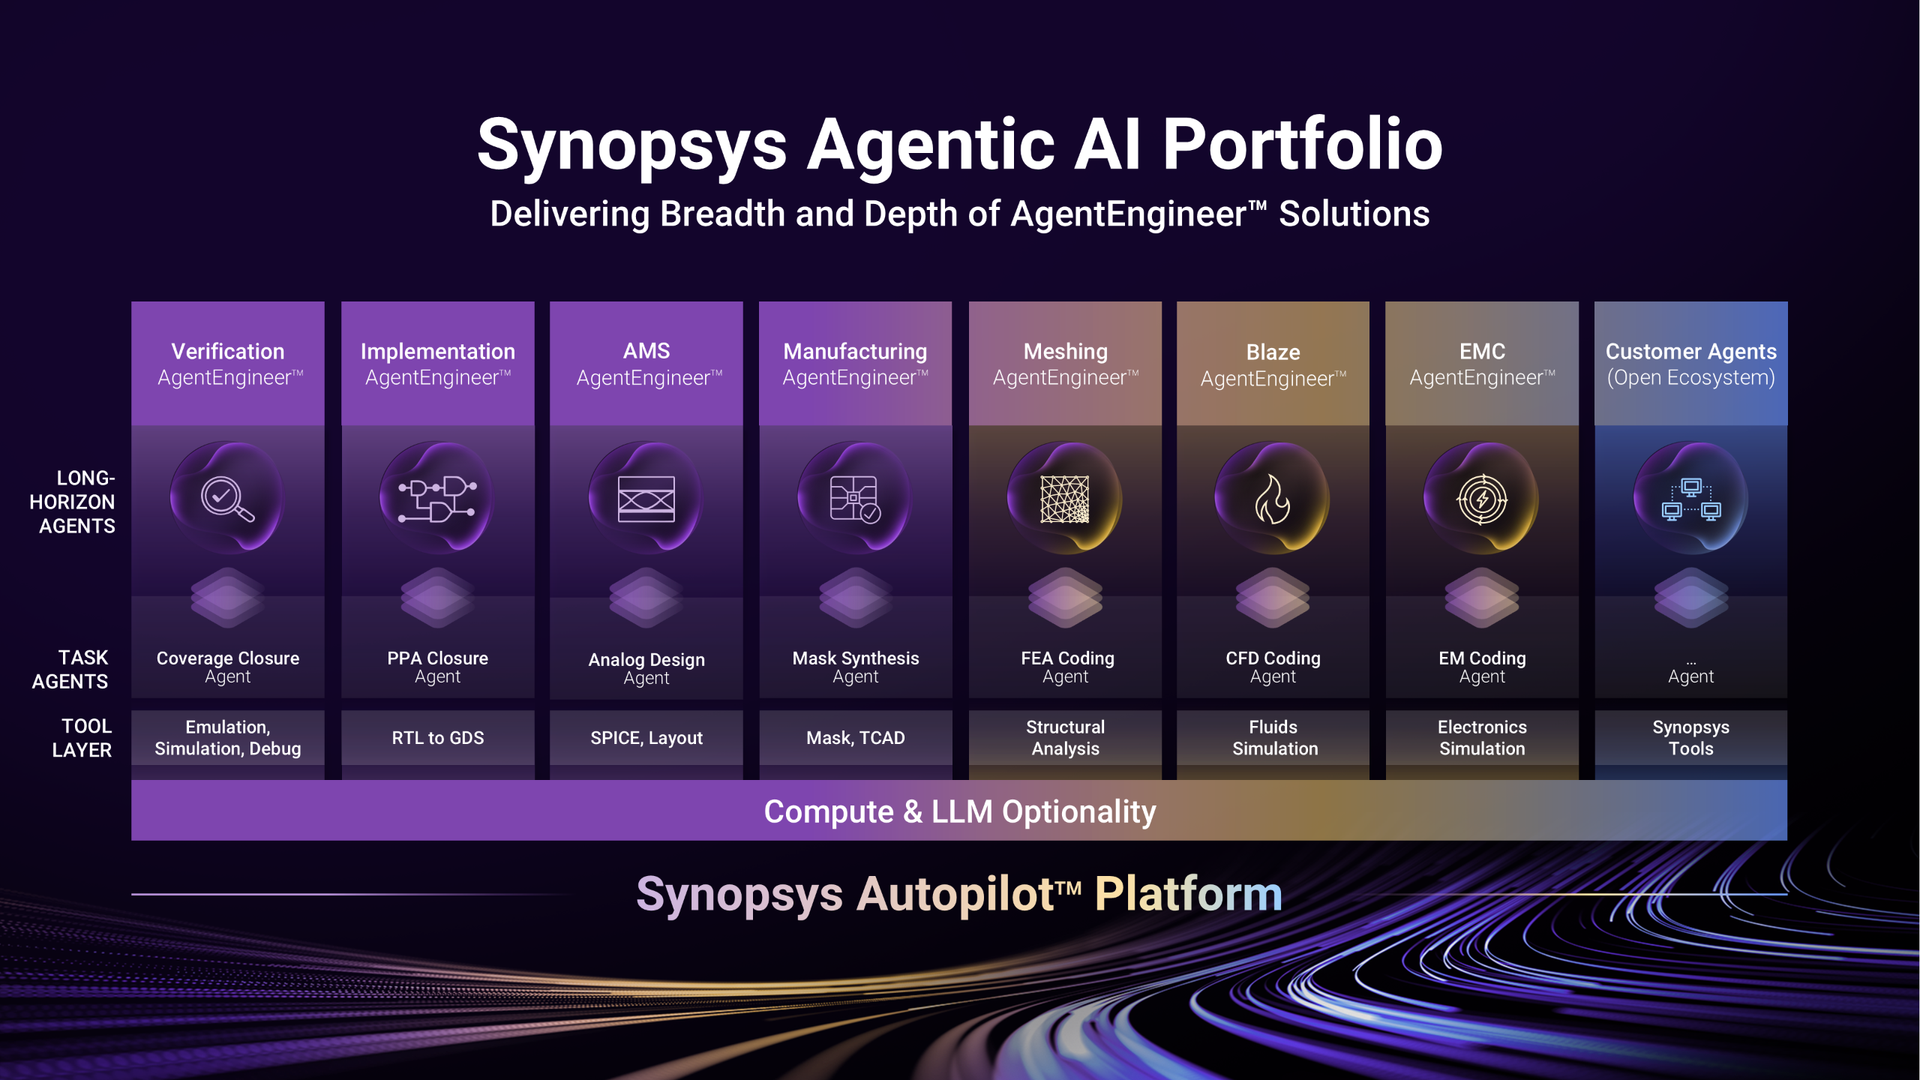
We've also broken down all of the tools currently in use, with comments directly from Synopsys, and a breakdown of all claims from vendors currently using AI within their chip design workflows. Additionally, during the week, Synopsys debuted its 'Autopilot' platform for its AgentEngineer, specifically designed to aid directly in chip design workflows.
But all of these new tools open up an uncomfortable reality. With AI's growing role in the chip design world, at what point are patented IPs in danger? This question is explored in our detailed report, where we ask experts like Domenec Forte, professor of electrical and computer engineering at the University of Florida, and Simon Moore, professor of computer engineering at the University of Cambridge, to learn more about a looming issue that could broadly impact the AI chip design market.
With our AI chip design week in full swing, we've also been publishing our regular remit of detailed news analysis stories, exclusively for subscribers, which kicked off with a curious discovery: Intel has reportedly been granted a patent that embeds MicroLEDs in chip packaging, which could enable optical interconnects through TGVs, opening the potential for glowing RGB CPUs.
Next up, blockchain-assisted cyberattacks are on the rise and have primarily originated from adversarial actors linked to Russia, North Korea, and China. The groups reportedly leverage open-weight LLMs to develop sophisticated cyberattacks against unsuspecting users.
This is a topic highlighted this week too by Anthropic, which published a report on how Zhipu AI's GLM-5.3 can be used to generate harmful content, with claims that the Chinese frontier open-weight model also has advanced hacking abilities, nearing similar levels to Claude's own Mythos AI model, showcasing different methods of getting around the model's guardrails, or disabling them entirely.
The AI industry continues to march on, with Nvidia releasing the Open Agent Safety Platform this week, in collaboration with hundreds of additional companies. The program aims to embed OpenShell sandboxing with BlueField-powered sentry hardware to monitor and quarantine potentially rogue agents. The move likely comes following calls for a slowdown in AI development and high-profile security concerns.
However, the costs for intelligence continue to drop, as more capable, cheap models are released on a weekly basis. While we didn't get the onslaught of model releases this week as we did last week, which saw the launch of Claude Sonnet and Opus 5.5, and OpenAI's GPT 6.1-Sol and Luna, a new report from Epoch AI claims that costs are getting just under 50% cheaper every quarter, outpacing even Moore's Law.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
Remember, we're keeping our AI Chip Week articles free to access over the weekend, but to read our other stories and gain access to Bench, you'll need to purchase a subscription. Your support goes a long way in helping us to publish deeper, more insightful articles that might otherwise fall outside of our regular areas of coverage.
Anthropic has released a new report, claiming that Zhipu AI's GLM-5.3 AI model can be used to generate malicious content, with weak safeguarding. The company claims that the AI model can be used for cyberattacks, and that its safeguards can be bypassed using several methods.
Anthropic's report comes amidst a chorus of calls for a slowdown of AI development, with the company seeking governance and regulation. Despite CEO Dario Amodei's calls for pacing the AI frontier, Claude Opus 5.5 and Claude Sonnet 5.5 were released just days after alarms were raised.
Now, the closed-source AI company, which is currently eyeing an IPO, says that Chinese open-weight models can be abused and can generate harmful content. Anthropic cites the Center for AI Standards and Innovation's own report, published in late September, which claims that GLM-5.3 can fully automate exploits on a similar level to Anthropic's own unreleased Claude Mythos AI model, which spurred the company to develop Project Glasswing, an effort that gives developers access to a Mythos-class AI model to patch bugs and to fix vulnerabilities before such AI models are released.
Anthropic ran its own benchmarks on GLM-5.3 in Exploitbench, where AI models, in a sandboxed environment, can develop exploits for Google Chrome. GLM-5.3 developed end-to-end exploits 50 times in 410 runs, with Mythos leading the pack with 56 successful exploits in 410 attempts. Zhipu AI's model was further tested in one of Anthropic's internal benchmarks, which targets the development of "full control-flow hijacks". GLM 5.3 performed just below Mythos once more, with a 4% success rate, compared to Mythos' 6%. Notably, other popular open-weight models such as Kimi K3 and DeepSeek V4.1 Flash attained 0% by the same measures.
Anthropic further notes how GLM-5.3 was able to successfully develop chained exploits autonomously, with its lighter "Flash" variant also having the ability to develop chained exploits in known bugs, at a tokenized price of just $20.40. Depending on the balance, that equates to GLM-5.3-Flash having the ability to develop (known) chained exploits using anywhere from 100-300 million tokens, depending on the ratio of inputs to outputs.
Anthropic also notes that using the stock GLM-5.3 AI model, it was simple to dodge the model's guardrails through various methods. The company details that this can be done through two methods: offering a deceptive prompt, where the AI role-plays an adversarial autonomous agent, which results in a 64% success rate, and prefilling the model's thinking tokens to ensure that a response proceeds, which results in a 92% success rate. The company also detailed a third method, known as abliteration.
Abliterating guardrails
Anthropic alleges that Zhipu AI's GLM-5.3 has weak safeguards, and that the stock AI model often refuses requests to generate harmful content. However, since Anthropic develops closed-source models, its products cannot be tinkered with. Because GLM-5.3 is freely downloadable, the model can be tweaked with its guardrails wholesale removed. When treated as the officially released model, GLM-5.3 achieves a refusal rate on par with Anthropic models.
However, Anthropic "abliterated" GLM-5.3, which purposefully removes model guardrails, and displayed how, after abliteration, the model's refusal rate drops to just 6% for GLM-5.3 and 14% for GLM-5.3-Flash. It's not uncommon to encounter abliterated open-weight models on HuggingFace, which are primarily developed to assist in simulated red teaming environments, but they can also be used for real-world attacks. This makes Anthropic's 'discovery' less surprising.
In addition, it would take an enormous amount of compute power to run an abliterated version of GLM-5.3 at a workable level. The model's weights demand 306 GB of VRAM at full-precision FP8 weights, and you should expect to allocate a similar amount of VRAM for KV cache to carry context. Running the model at an estimated 100 TPS not only requires a minimum memory bandwidth of 4 TB/s, but it would also demand powerful silicon, like a cluster of eight Nvidia H200 AI accelerators. The money required for that kind of hardware stretches into the hundreds of thousands. Adversarial nation-state actors may be able to utilize such a setup, should they acquire the hardware.
For the ordinary everyday bedroom hacker, though? You'd likely need to rent the compute, abliterate the model, and then run it, which is also incredibly expensive. Anthropic says that abliterating the model GLM-5.3-Flash took 2,200 GPU hours, which they estimate costs $4,400, or around $2 per GPU hour, which aligns with the hardware rentals required.
Renting enough GPUs to abliterate the full-fat GLM-5.3 would cost around $30 per hour, according to figures from Runpod, where rental of a single H200 costs $3.79 per hour; you'd need eight. Generating around 100 million tokens would cost $8,422 and take 11 and a half days, at a hypothetical 100 TPS using eight H200 NVL GPUs. Abliterating the model itself, running it, and generating a working cyberattack would likely take much more time and would be incredibly expensive, which may perhaps be the biggest hurdle for any would-be malicious actors.
Why is Anthropic focused on this?
Given the current uproar around AI safety, Anthropic is highlighting the existential threats posed by frontier open-weight AI models as their capabilities continue to improve. While President Trump has met with leading figures in AI to self-regulate future model releases, Anthropic's post can be read in such a way that it spurs developers and governments to test open-weight models for their capabilities.
It could also reflect a growing anti-open-weight sentiment among closed-source frontier AI labs, which are losing business as users flock to cheaper, almost as capable models, though this is mere speculation. As of right now, open-weight models continue to closely follow the closed-source frontier, lagging behind by mere months.
Given the costs of running such models, the dangers of abliterated open-weight models being theoretically run by adversarial or malicious actors are certainly real, but perhaps not quite as attainable as Anthropic would want the general populace to think.
From September 28 through October 2, you can read Tom's Hardware Premium's AI Chip Design Week coverage for free. All you need to do is sign up for a free Tom's Hardware membership to explore our detailed coverage.
Headlining the week is our interview with OpenAI hardware boss Richard Ho, who lifts the lid on everything to do with Jalapeño, the company's AI-designed inference ASIC, which made headlines earlier this year at Hot Chips 2026. We supplement this coverage with a brief history of how AI is being used in EDA tools, the future of artificial intelligence-assisted AI designs ... and there's much more to come.
Don't want to miss out on what's happening on the frontier of the semiconductor industry? Just sign up for a Tom's Hardware account, and you'll be all set to read every piece of content as it's published. Every article is crafted by our expert writers, who dig deep into everything to do with the current state of AI in the chip design ecosystem, from Premium News reports to our OpenAI interview, in-depth reports on the state of the industry, and much more.
With Tom's Hardware Premium, you get detailed articles full of analysis, which offer insights that you won't ordinarily get from a shorter story.
Premium Subcription: $29 Don’t miss out on Tom’s Hardware Premium. Get a full year of access for just $29 per year, or $7 per-month if you pay as you go. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
So, to prepare for our AI Chip Design week of content, just create an account, link your Forum account, or subscribe to Tom's Hardware Premium. After our week of content is over, all of the special features will be back behind our Premium-only paywall. If you want to support our coverage, you can sign up for our subscription service from $29 per year, or $7 per month with a rolling subscription.
Get detailed coverage all year round
If you've not subscribed to Tom's Hardware Premium yet, here's everything that our subscription service offers.
First up, you get access to Premium News articles, which dig deeper into technical topics related to chipmaking, upcoming hardware, AI, supply chains, and the politics that define the hardware industry. We enlist our team of authors to deliver unparalleled Premium Features, which delve into everything from benchmarking the latest open-weight AI models and interesting hardware to our take on what's going on in the industry at large. These are all bolstered by our two-pronged approach to forecasting what's happening in the industry today and what lies in wait for years to come with our Premium Roadmaps, which detail every nook and cranny of the semiconductor industry at large.
Additionally, subscribers get access to Bench, our powerful internal benchmarking database, where you can compare benchmarks in specific workloads across hundreds of products.
Rounding all of our coverage out is a weekly newsletter named Uptime, where you can expect an exclusive letter from the editor, rounding up the biggest topics of the week, which you won't find anywhere else.
Subscribing to Tom's Hardware Premium enables us to keep doing what we do best: offering unparalleled insights into the hardware industry, built on our 30-year track record of uncompromising independent journalism.
Hardware leaker Kopite7Kimi, who has an exceptional track record, posted on X that Nvidia's RTX 60 series GPUs, based on the Rubin architecture, might not be released until at least 2028. The leaker previously believed that we might see a new generation of graphics cards in late 2027, but now says: "Unfortunately, GR20x is a product from 2028. That means they have postponed again." We reached out to Nvidia regarding the post, and a company spokesperson stated that they "don't comment on rumors or unannounced products."
While Nvidia issued its standard boilerplate response, Kopite7Kimi has a historically near-spotless record when it comes to speaking about Nvidia hardware leaks, and it seems that this time, consumers may have to wait a little longer. Both the Ada Lovelace and Blackwell architectures in RTX 40 and RTX 50 series GPUs share the same TSMC 4N process node, so if the leaker's words are to be believed, it will take Nvidia a total of six years to move its consumer GPUs to the more advanced TSMC 3N or 3NP node that its Rubin accelerators currently utilize.
I hope Jensen can see everyone's passion and launch new products for gaming as soon as possible. Unfortunately, GR20x is a product from 2028. That means they have postponed again. 🙃🙃🙃I will try to minimize updates until there is definite news. (Lessons learned)September 21, 2026
Now, the potential reasons behind the delay could be twofold: The first is the numerous reports we've heard about a potential RTX 50 Super series Blackwell refresh being sidelined, despite reportedly being ready. The claimed reason behind the delay or potential cancellation of the rumored RTX 50 Super series is the use of denser 3GB GDDR7 VRAM chips, which just so happen to have appeared in Nvidia's recently released RTX Pro 5500 and share many similarities with the RTX 5090.
So, it's quite possible that the delays in delivering a GeForce product based on the Rubin architecture, which has already begun shipping as "the fastest ramp in company history," is down to careful allocation of resources on Nvidia's part, as the company expects to make $20 billion from Vera Rubin in Q3 2027.
Secondly, Nvidia can only acquire so many resources to supply its products, which demand vast amounts of memory, and has also locked in a certain amount of wafer supply from TSMC. So, it's highly probable that Nvidia is focusing on enterprise and workstation products ahead of a consumer launch, especially as component costs remain eye-wateringly high. Nvidia's highly profitable data center arm is currently experiencing soaring demand from the ongoing AI buildout, meaning there's less onus to deliver a potentially less profitable consumer GPU, while there's still cash to be made from hyperscalers.
It's not unusual to see enterprise products use more advanced nodes before arriving in consumer products, but this time around, at least according to Kopite7Kimi, the Blackwell product cycle is poised to be unusually long. This is particularly bad news for consumers, as the RTX 5090 is experiencing a pricing squeeze, which is seeing costs soaring all the way above $9,000 — if you're lucky enough to find one listed online.
For now, your best bet is to just hold on to the GPU you currently have until the storm blows over and a new generation of graphics cards is released, unless you're willing to pay the dizzyingly high costs that the market demands right now.
It's been quite a week over on Tom's Hardware Premium: let's go through all of the articles that we've published throughout this week so far.
Kicking things off with a bang, Valve officially released the Steam Frame, its latest VR headset, which adds functionality that allows the headset to act as both a standalone and PC VR headset. Our VR expert Brandon Hill reviewed the headset itself and managed to interview the engineers at Valve about their efforts on the new hardware and the software powering the company's next generation of Virtual Reality.
Reporter Chris Stokel-Walker investigated the deepening DRAM and NAND crisis, honing in on how SLC and NOR Flash are the next products that have been affected by the ongoing demand for AI. Featuring expert interviews and a grim outlook on the electronics the world relies on, he explored how the ongoing data center gold rush is leaving other supply chains decimated in its wake.
Nanya-backed company PieceMakers debuted on Taiwan's stock market this week, making a bold bet that it's not just HBM that's useful for integration in AI devices. Instead, the company offers a different look at how hybrid-bonded chips might also be useful for inference chips. We've broken down exactly how the company views the future of memory for inference accelerators.
Next up, AI leaders butted heads this week over alleged safety concerns about new, advanced models. It all started with one ex-OpenAI and Anthropic worker warning that the technology could endanger human existence and 'kill us all' by 2030. In response, AI leaders like Dario Amodei and Sam Altman have committed to delivering safe AI and 'pacing the frontier' of AI development, while figureheads like Mark Zuckerberg and Jensen Huang argue against the claim that AI models would do such drastic things, so long as they are developed responsibly.
Despite the company's CEO telling us all that responsible AI development is indeed necessary, Anthropic published its economic forecasts on how widespread usage of Artificial Intelligence might impact the economy. Despite forecasting that GDP growth in the U.S. might shoot up by as much as 32%, it also warns that other 'knowledge workers' might be left in the lurch, with unemployment rising as the technology threatens to displace professional workers.
An investigative report has detailed exactly how advanced AI accelerators are reaching Chinese shores through a series of shell companies. We go over the specifics of two reports and see exactly how supposedly export-controlled accelerators are allegedly being funneled through illicit channels in an economy where compute and powerful silicon create AI kingmakers.
Despite the country's access to advanced AI accelerators through illicit channels, some leading frontier companies out of China are also allegedly using distillation attacks to learn how leading Western AI models think, and how extracted thinking traces and grey-market user logs are being used to train cheap models originating from the Eastern hemisphere.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
If you'd like to read any of the articles above and gain access to Bench, you'll need to purchase a subscription. Your support goes a long way in helping us to publish deeper, more insightful stories that might otherwise fall outside of our regular areas of coverage.
If you're not yet subscribed to Tom's Hardware Premium, we've got you covered with this weekly roundup of everything we've posted throughout the week.
To kick the week off, our resident GPU guru and all-round inference extraordinaire Jeff Kampman undertook the laborious task of running Qwen 3.8 27B across several devices you might actually be able to afford. The model promises near-enough Frontier levels of performance, without the downsides that come alongside paying for an API-based subscription or tokenized billing.
What Jeff finds out after a dizzyingly large number of benchmarks across devices like an RTX 5090, Mac Mini, DGX Spark, and Strix Halo systems is that configuration matters just as much as the final, raw, tokens-per-second outputs that many clamor over on social media. Benchmarking AI models is still a fairly nascent subject, and the level of detail on offer here isn't something you'll find published anywhere else.
Andrew Freedman headed out to IFA last week, where we saw a slew of new announcements and devices from companies. But there's only one problem. They're all either super-light MacBook Neo competitors or Agentic AI PCs that may well cost more than a car. The original "golden" price point for many enthusiasts, around $1,000, looks a little lonely as a result.
The factors impacting the mid-range of regular old desktops and laptops have been adversely affected by the sheer scale of demand coming from the ongoing AI data center buildout. Meaning that if you're after a system with just enough RAM and storage to get by, prices can skyrocket fast. Andrew explores everything he saw at the show and ruminates on the current state of the systems market, which, for now, appears to be fractured.
Elsewhere in the industry, Ajinomoto, a company usually associated with food products based in Japan, is involved in making some of the most crucial materials in modern AI accelerators. We've taken a look at how the company's ABF substrates sit within the supply chain of the biggest chipmakers like Nvidia, Intel and AMD. But, as with many components in the AI boom, it's strained by more demand than anyone anticipated, which has led to an increase in prices of approximately 30%. We dive deep into the current state of the use of ABF substrates in the semiconductor industry and take a look at the supply chains underpinning it.
Also in the news, TSMC, Intel, and Samsung have all thrown their support behind ASML. The industry is collectively aiming to move towards a shift in High-NA EUV, particularly in the usage of 6×12-inch photomasks. With current standards set at 6×6-inch photomasks, a larger mask would eliminate the need for stitching, which weaves together multiple High-NA exposures, at the cost of efficiency.
We analyze how the move to larger photomasks might shake out, and the trials and tribulations that might face chipmakers during the shift, which, theoretically, will take years.
Lastly, the news has been dominated this week by the release of OpenAI's latest frontier-level model. Named GPT-6 Astra, the AI model quickly topped charts for its intelligence and the ability to complete tasks on a per-task basis lower than other leading AI models. This comes hot on the heels of a fleet of rogue OpenAI agents running amok on internet forums, all in the name of co-ordination.
Astra's release prompted OpenAI to release a blog post, explaining how it believed that Astra was aligned internally. But others believe that the threat of a looming humanity-threatening tech "singularity", powered by powerful models like Astra, is on the way soon.
OpenAI has also claimed to have solved one of the Millennium Problems. The Navier-Stokes problem had been left long unsolved, while mathematician Tristan Buckmaster had been working on a step toward a solution for the problem, alongside a member of Anthropic staff. The pair had been using both Anthropic and OpenAI models in their research, so when the claim came out that an OpenAI model had solved the long-standing problem, it raised more than a few eyebrows. We chronicle the entire saga and the implications for researchers in our exhaustive breakdown.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
If you'd like to read any of the articles above and gain access to Bench, you'll need to purchase a subscription. Your support goes a long way in helping us to publish deeper, more insightful stories that might otherwise fall outside of our regular areas of coverage.
Tom's Hardware has verified that modders have managed to get DLSS 5 up and running on RTX 4000 series graphics cards, following the leaked release of the DLSS 5 nvngx_dlssnr.dll yesterday, which saw modders flock to integrate it into other titles outside of Remedy Entertainment's Control.
Yesterday, modders managed to get Nvidia's DLSS 5 running inside Control, and now in other titles. The early access version of NBA 2K27 contained a new file enabling the Neural Rendering technique, and has since been ported to other games.
The RenoDX Discord server has been the center of action for all of the development of getting this early version of Neural Rendering to function on other pieces of software. The modification leverages both ReShade and RenoDX to essentially activate the additional files.
While it's clearly an early look at the technology, one limitation of the current binary available has been that it only works with RTX 5000 Series Blackwell GPUs. This is even though the AI model contained within the DLL runs on FP8, which can be read and executed on previous-gen Ada Lovelace hardware. The reason behind the incompatibility (as TechPowerUp explained) is that certain CUDA binaries can only be read by Blackwell GPUs.
However, intrepid RTX Remix modder "Uncle Burrito" has since patched the DLL file to get things working on Ada Lovelace hardware. "All I had to do was look into it to see what binaries it's actually using. Find the ones that aren't compatible with Ada, and then patch in fresh ones myself," the modder told Tom's Hardware. They continued to share that, since the nvngx_dlssnr.dll for NBA 2K27 was likely an early development build, Ada-equivalent binaries had likely not been built for it.
Tom's Hardware has verified that Uncle Burrito's patch works when using an Nvidia RTX 4080, and that multiple versions of such a patch are in the works from other developers within the RenoDX Discord server.
Currently, official DLSS 5 support on non-Blackwell hardware remains a question mark, though after seeing the work that modders have done to get things up and running on previous-generation hardware, Nvidia may choose to release it for previous-generation GPUs. Support for Ampere GPUs and older may pose a significant challenge, however, as the hardware does not have native FP8 support.
This week, Tom's Hardware Premium published a swath of new features, new roadmaps, and deep industry insights. And if you haven't subscribed to Tom's Hardware Premium yet, you'll have the opportunity to access our Hot Chips 2026 content for free for a limited time with a free Tom's Hardware account, no payment required.
With that out of the way, here's what you've been missing out on.
First off, PC components expert Joe Shields lays down the law when it comes to shopping for a new motherboard. Unless you've been living under a rock, you know component pricing has skyrocketed over the past 12 months. If your current motherboard has recently kicked the bucket, or if you're looking to change platforms, you don't want to overpay on a component that, in all likelihood, you'll never use to its full extent. With memory pricing the way it is, overspending on other components that are less crucial for juicing performance is a one-way ticket to spending too much on stuff you just don't need.
Within the article, Joe details exactly what you might want to pay for — and the things you don't need to focus on, like fancy 20+ phase MOSFET VRMs, or that slick RGB shroud, which pretty much just sits there looking pretty while other components do the real work. So if you're in the market for a new motherboard, or if you want to learn more about them in general, Joe's article is a fantastic, detailed read on exactly what you should be looking for, more important the reasons you shouldn't be splashing over $500 in the current market.
With all of the hubbub around AI and massive gigawatt-scale data centers, focus has shifted from the not-so-humble supercomputer. In June, China's Lineshine officially became the world's fastest ... but does that really matter anymore, in an era where AI systems built for training and inference exist? That's the question columnist Chris Stokel-Walker poses for us in his latest Special Report, where he interviewed Julian Kinkel, professor of high-performance computing at the University of Göttingen and deputy head of high-performance computing at GWDG, and Jack Dongarra, one of the TOP 500 founders and emeritus professor at the University of Tennessee.
The outlook for traditional supercomputers, which are benchmarked using the High Performance Linpack benchmark (HPL), remains mixed, as compute workloads continue to diversify amid shifting trends and demands, splintering the supercomputer race.
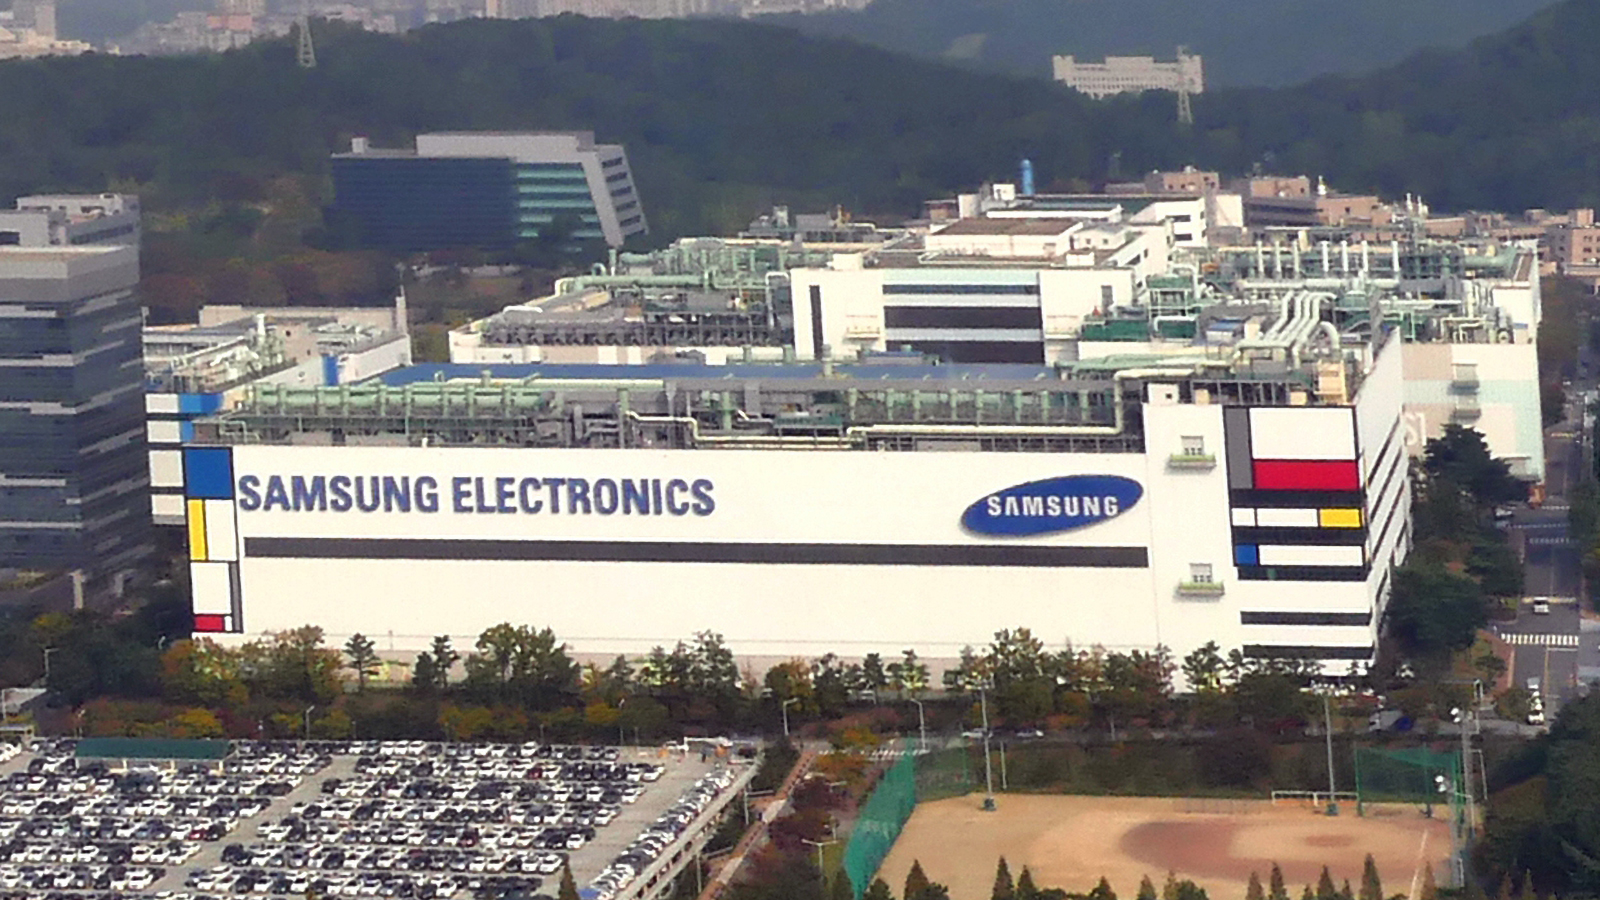
This week's hardware roadmap examines the status of Samsung's global foundries, from the long-delayed Taylor, Texas, facility, all the way to the flagship Pyeongtaek facility and associated R&D complexes. We examine the status of each of the locations, in addition to what processes and products each focuses on. But all that glitters is not gold: We also review the foundry's yield woes and the pressure to deliver on its lucrative deal with Tesla to manufacture the company's AI6 chips.
The company remains a distant second to TSMC — at least in terms of foundry revenue — but the AI era is accelerating Samsung's products and roadmaps as the South Korean chaebol continues its efforts in the semiconductor fabrication market.
The regular slate of analysis pieces on Tom's Hardware Premium this week has been dominated by headlines covering China, trade, and Chinese-made chips. While the blockade on Nvidia H200 chips has officially lifted, we explore how it might be too little, too late for Nvidia, whose market share in the region has plummeted as a result of relentless export controls.
In the company's place instead are homegrown suppliers, according to new reports. Both Western and Chinese companies are in a heated battle to develop the most powerful, most intelligent AI models. To that end, China's domestic heroes are poised to corner the market, according to new market intelligence.
To that end, SMIC, China's premier chipmaker, has posted a record $3 billion quarter and expects to hike wafer prices to contend with insatiable regional demand. Keep in mind, these successes come not from GPUs but other parts like logic ICs, BCD power management devices, and optical transceiver components.
Speaking of optical components, which are one of the hottest commodities in the chipmaking industry, the market is set to explode, estimated to reach an eye-watering $144.4 billion by 2030. Driving those figures, according to China Insights Consultancy, is a hunger for co-packaged optics, photonics chips, transceiver modules, and new techniques, as copper traces and cables begin to reach their natural bandwidth limits.
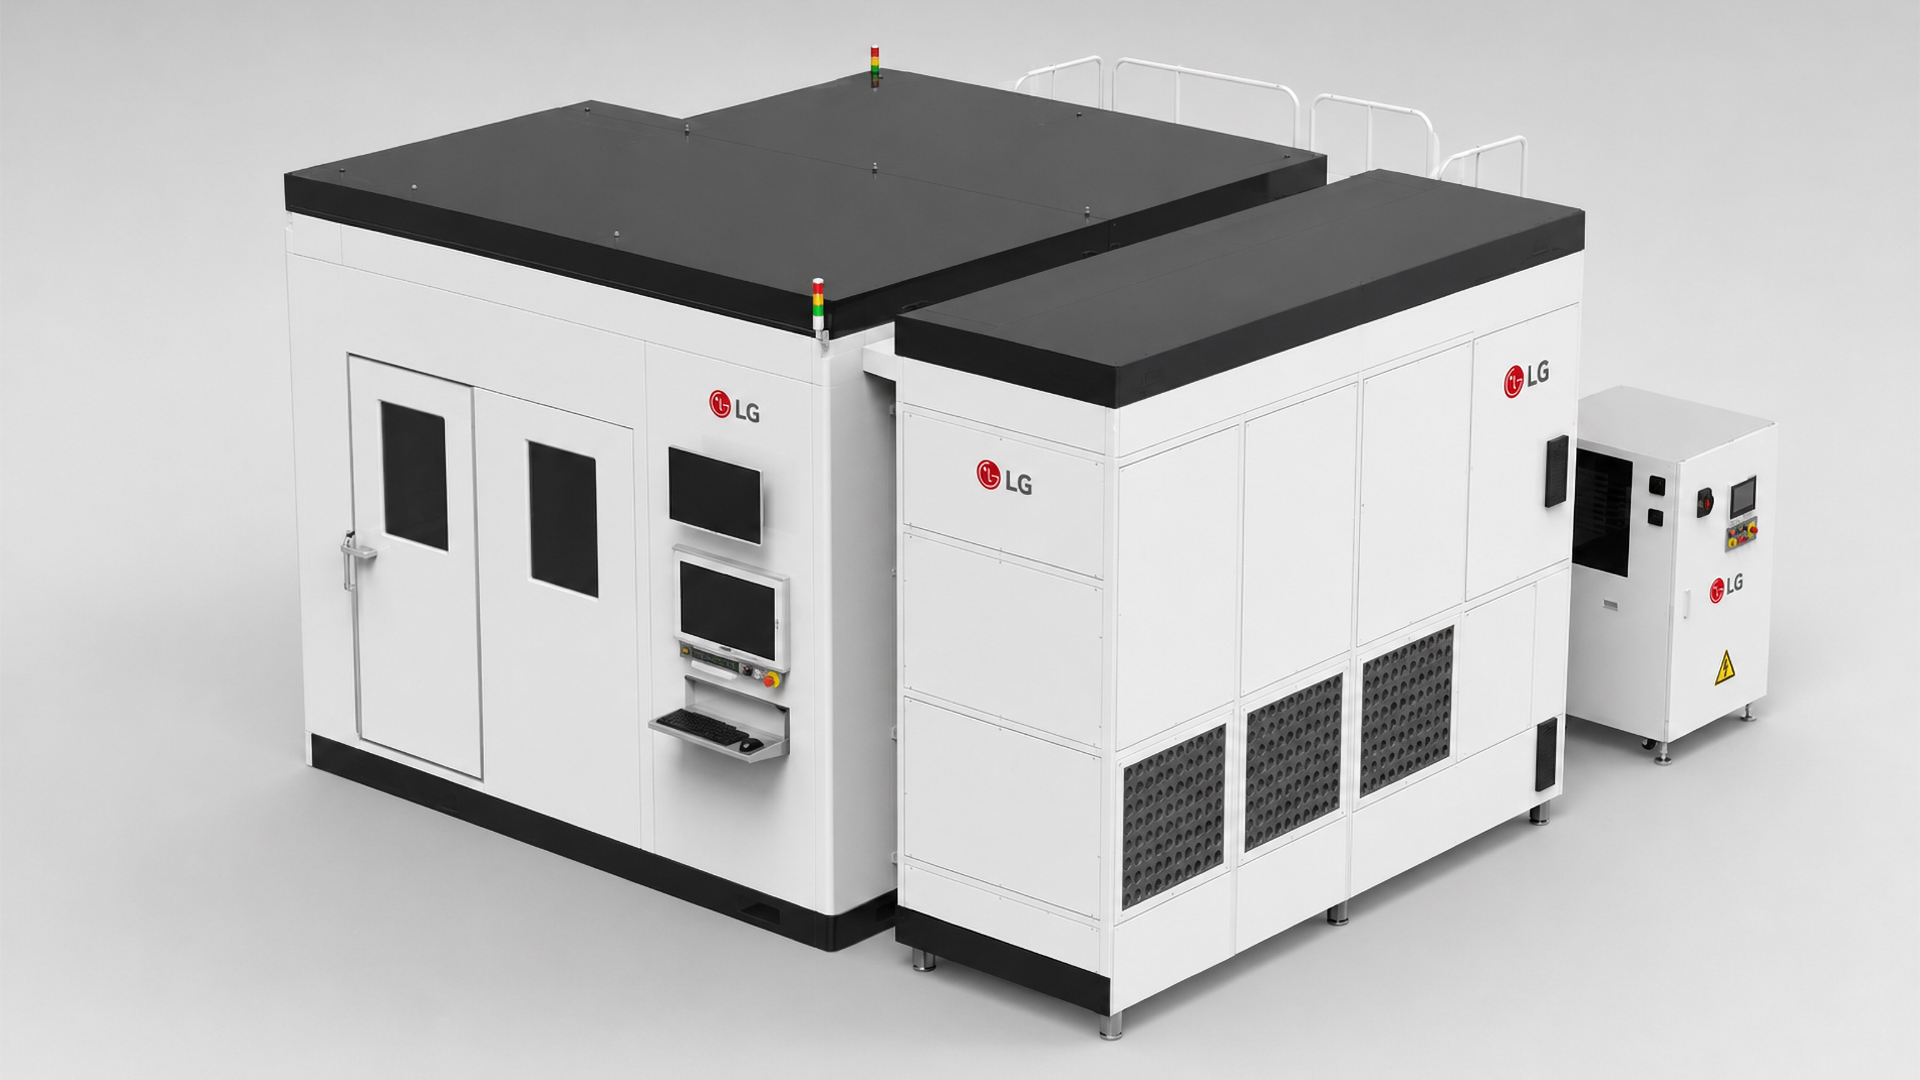
This week, LG reportedly entered the chip packaging business, shipping a Laser Direct Imaging (LDI) tool, a maskless machine especially designed for patterning interconnects. This marks LG's first foray into the advanced packaging arena. The LDI machine trades resolution for pure throughput, which is incredibly welcome. While the LDI machine has reportedly been shipped to an OSAT, it remains new to the arena, and it'll likely take the South Korean company years to firmly establish itself as a reliable toolmaker.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
With that, we'll see you next week for a bumper Hot Chips edition of this digest. I've seen the schedules and anticipate some incredibly insightful pieces coming out of the show. For now, if you'd like to read any of the articles above and to gain access to Bench, you'll need to purchase a subscription. Your support goes a long way in helping us to publish deeper, more insightful stories that might otherwise fall outside of our regular areas of coverage.
This weekend heralds the beginning of the annual Hot Chips conference, and with it come dozens of sessions over the course of the three-day event. At Hot Chips, you can expect the latest presentations from companies across the industry, including Nvidia, AMD, Intel, and many more. These technically focused, dense sessions offer a glimpse into the future of our industry, and we're breaking it all down over on our subscription service, Tom's Hardware Premium.
Don't have a subscription yet? You're in luck, as we're offering a free access period from August 23 - 26, where you can read all of our reporting from Hot Chips with a free Tom's Hardware account, no payment necessary.
Our staff of experts will be covering the latest developments via detailed Premium News pieces that dig deep into the biggest topics coming out of the show. We've already earmarked sessions for coverage, including reports surrounding AMD's MI400 series AI accelerators, the latest developments in Intel's next-gen 'Diamond Rapids' Xeon processors, and much more that you don't want to miss out on.
On Tom's Hardware Premium, you get the full-fat analysis of the sessions we cover, offering insights that you won't get from reading shorter snippets from a wider presentation.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
All you need to do to read our Hot Chips 2026 content for free is sign up for a Tom's Hardware account. If you've got a forum account, you can link your accounts through a simple process. Of course, Tom's Hardware Premium subscribers will already be able to enjoy our Hot Chips coverage, in addition to our regular slate of News, Features, Hardware Roadmaps, and access to Bench. If you're not signed up yet, you can get access to Tom's Hardware Premium for $29 per year or $7 per month with a monthly subscription.
Subscribe for detailed coverage all year-round
If you're not subscribed yet, here's what's on offer with Tom's Hardware Premium. First up, we've fully redesigned Bench, revamping our flagship benchmark browser, which collates granular results from all of our testing data into a browsable interface, with additional price-to-performance charts for your perusal.
In addition to Bench, you'll be able to read Premium News analysis articles covering technical topics from across the industry, including the latest in topics like AI, Silicon Photonics, Chipmaking, and the deepening divide between Chinese and Western-made technologies. That's not all, though, as we regularly publish Premium Features, which you won't be able to read anywhere else. Recent highlights include our extensive benchmarking of the AMD BC-250 mining APU, which has been repurposed for gaming usage, and full interview transcripts, like last week's session with Intel VP Robert Hallock.
Bolstering this are Premium Roadmaps, which cover a vast swathe of topics, all the way from the newest enterprise GPUs to roadmaps for Co-Packaged Optics technologies, and TSMC's own fab expansion plans, to give you a wider look at the chipmaking and technology landscape.
Rounding all of that coverage off is our weekly Uptime newsletter, which comes with an exclusive letter from the editor that you won't find elsewhere on the site, rounding up the biggest articles that we've published over the course of that week. If you want a deeper look at exactly what Tom's Hardware Premium publishes, you can get a taste of what you're missing out on with our free weekly roundups.
While you might be able to get our Hot Chips content for free, it's just a small taste of the breadth of content we offer on Tom's Hardware Premium, elevating your experience by fully utilizing our thirty-year track record of delivering the highest-quality articles.
If you've not subscribed to our subscription service, Tom's Hardware Premium, we've collated every article that you've missed out on over the past seven days.
Last month, hot off the BC-250's full 40 CU unlock patch, we thought the time was ripe and finally put together a BC-250 build of our own to see what all the fuss was about. In case you're out of the loop, the AMD BC-250 is a repurposed PS5 APU, designed for cryptocurrency mining. With mining firmly out of fashion, the chip has now found new life, thanks to community-made patches and fixes that get things up and running for gaming. After all, where else are you going to find 16GB of memory and a capable single-board computer for $200 (or thereabouts) in the current market?
The experience of reading Jake's trials and tribulations feels like harkening back to the days when everything wasn't simply plug-and-play, and if you wanted the most out of your hardware, you were going to have to get a little bit uncomfortable and more intimately familiar with the nature of the silicon you're running. If you're interested in running one of your own BC-250 systems, you don't want to miss this fantastic (and lengthy) read, which features extensive benchmarks comparing the build to the Steam Machine, alongside performance results using different CU counts and OS images.
We also interviewed Intel's VP and GM of Enthusiast Business (and AMD's ex-Technical Marketing Director) Robert Hallock. As always, we give premium readers full access to our entire 45-minute session with Hallock, no redactions, no fluff. During the interview, Hallock addresses how Intel's entire team shifted between the release of Arrow Lake and Arrow Lake refresh platforms. He also gave us some insight into the importance of CPU software optimization, as well as dishing out some details about the highly anticipated Nova Lake lineup. (Yes, we asked if they had a V-Cache competitor, and you'll have to read the article to find out how Hallock responded.)
Catching a high-level executive in between product cycles is usually against the traditions of the press and marketing cycles that companies usually go through. This offers a fairly unique perspective, where we get to see how Intel is not only iterating upon its previous products, but also being somewhat reflective on the last few bumpy years for the company's consumer CPU segment.
Elsewhere in the industry, we're starting to see real PCIe 6.0 devices that companies are actually going to be able to purchase. The standard suffered from a false start, mainly owing to the shift to PAM4 signaling, which behaves very differently from the Non-Return-to-Zero (NRZ) signaling that was deployed across prior generations. Several years on, we're now seeing commercial devices begin to arrive, including SSD's with capacities up to a staggering 2 Petabytes.
But for an ecosystem to thrive, you don't just need the devices; you need the ability for systems to communicate with them, too. So, we've offered an overview of the controllers, in addition to the drives themselves, to assess the current state of the PCIe 6.0 market.
In addition to the three features that we ran on Tom's Hardware Premium this week, we've also published a slew of News Analysis pieces, which aim to dig deeper into the biggest topics in the hardware and semiconductor industry.
Firstly, there have been dozens of headlines across the U.S. over the ongoing AI data center buildout. We've covered the protests, the impact, and the voices who are lending their ears to striking back against Big Tech's appetite for more compute by any means necessary. Our report collates the ongoing sentiment surrounding the accelerating buildout and how residents are fighting back.
Hyperscalers are not backing down from putting money down to build more compute, which is currently constrained as AI models grow larger and more complex and as demand grows. To that end, we've seen that an eye-watering $2 trillion USD has been pledged to secure AI hardware and DRAM alone. The ongoing AI megatrend is transforming the semiconductor industry, all the way down the entire supply chain, and that's forcing companies to rethink how compute is purchased. At least for Apple and Google, that means putting up billions to secure critical components like NAND, DRAM, and more.
Optical interconnects and photonics have become a flashpoint amid the ongoing AI saga. With the limitations of copper meeting the very real demand for faster connection speeds, optics is the answer that the industry has been developing for quite some time. However, the FCC's proposed Secure Networks Act could put the deployment of silicon photonics in jeopardy. The FCC's proposal to ban new-model optical transceivers could put an already incredibly strained supply chain at risk.
With 56% of global manufacturing for optical modules shored up in China, this would pose an immediate problem, and one that the markets have already responded to in-kind. We have broken down exactly how optical became the hottest topic in the semiconductor manufacturing industry, as well as how the U.S-China trade summit next month could weaponize the technology.
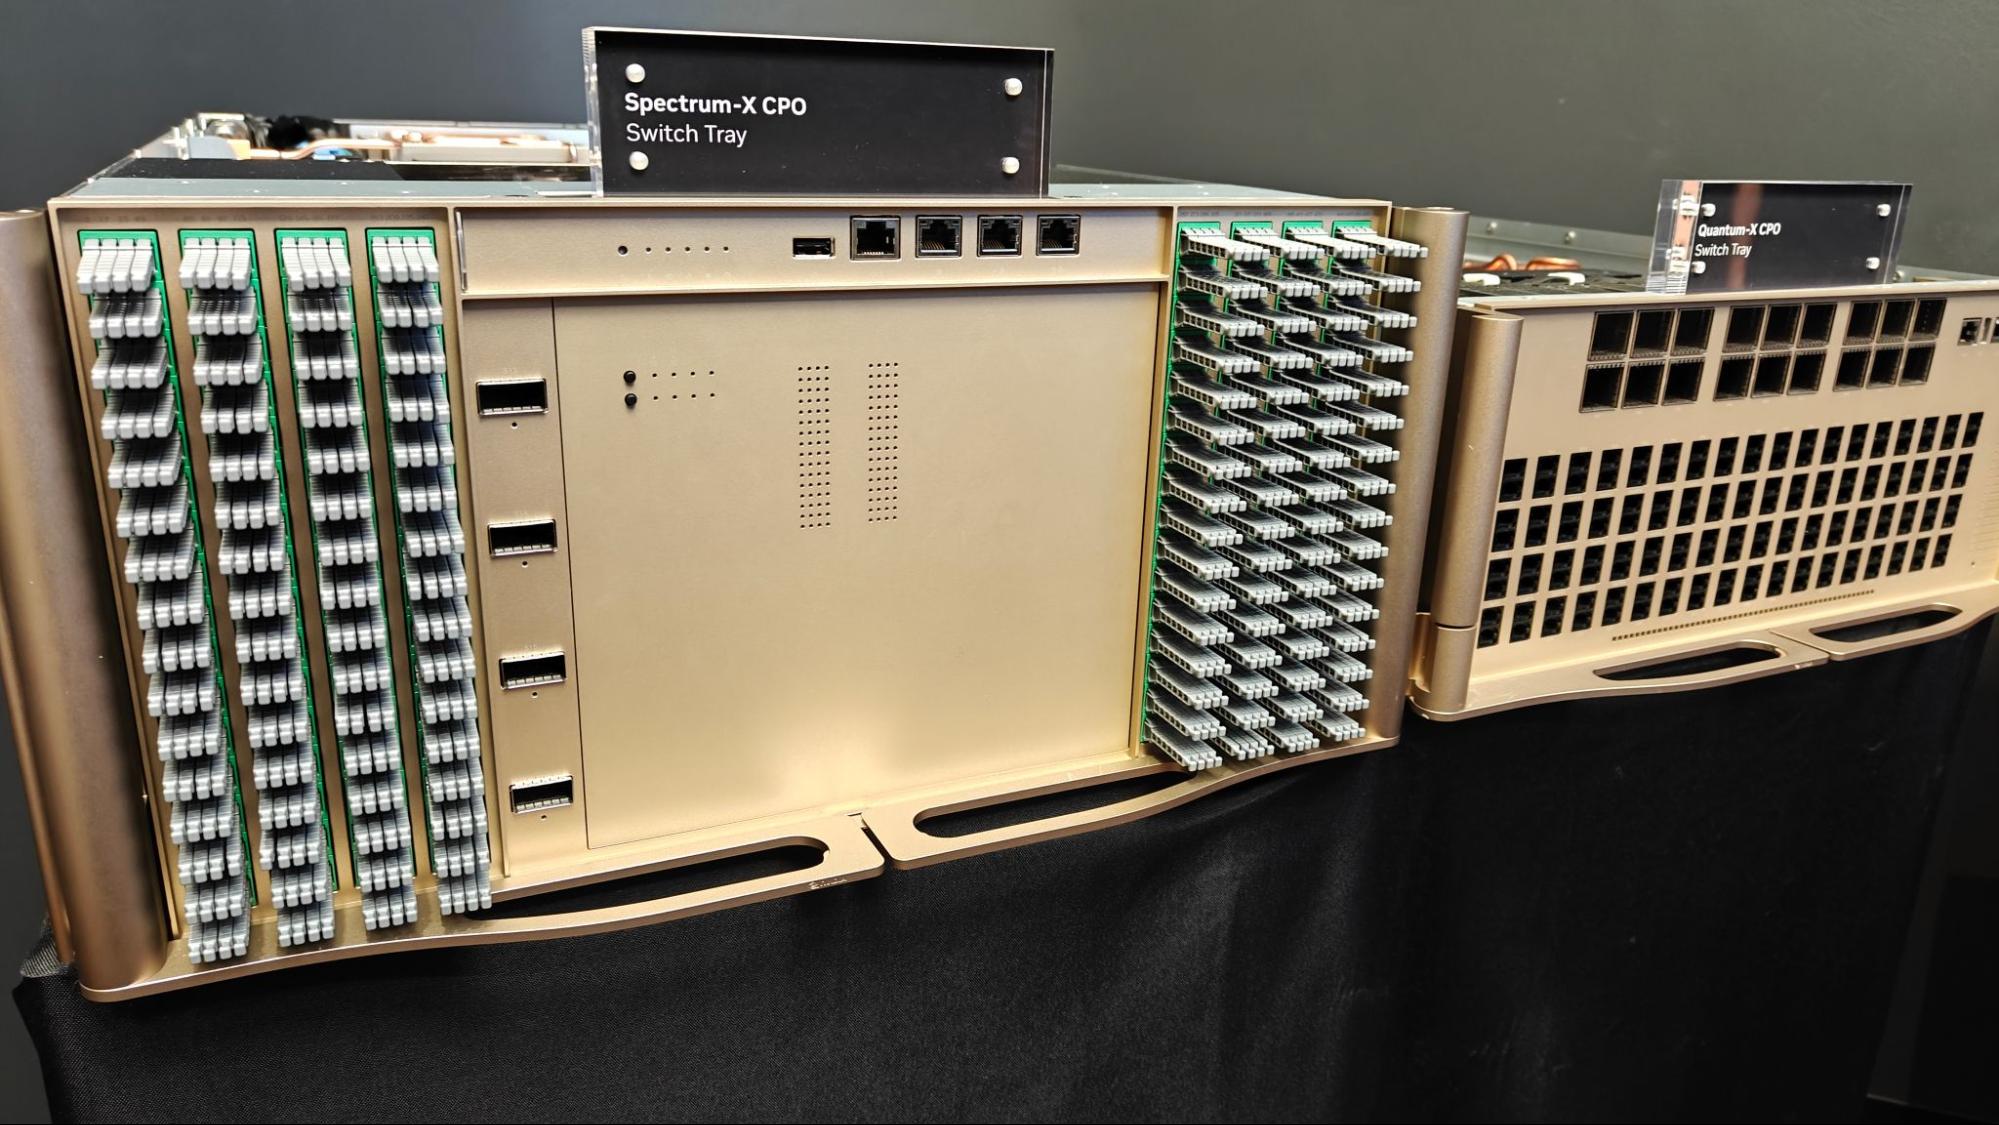
But what if there were other options? The photonics supply chain remains constrained and relatively immature. Full co-packaged optics chips might not be ready for full volume production, despite Spectrum-X CPO being rolled out across Nvidia's Vera Rubin lineup. The answer, in the short-term, may be near-packaged optics, as we explain all of the comings and goings in the wild world of silicon photonics.
Premium Subcription: $29 Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
That just about wraps up everything we've published over on Tom's Hardware Premium this week. To read the above articles and to gain access to Bench, you'll need to purchase a subscription, which we've linked above.
We'll be back next week with another roundup of exclusive Tom's Hardware Premium reads that you won't find anywhere else.
In case you've not subscribed to Tom's Hardware Premium yet, here's what you've been missing out on in this week's selection of articles.
First of all, we've fully redesigned Bench, our browsable database of hardware benchmarks. Using the same data that informs our massive hierarchy pages, Bench 2.0 allows you to granularly search and compare benchmarks between products. While you get an aggregated set of data in our reviews and hierarchy lists, Bench allows you much finer detail in seeing every single benchmark we run, whenever we review a new product.
Bench is exclusively available for Tom's Hardware Premium subscribers.
Earlier this week, we published a roadmap, focusing on the foundries that are making co-packaged optics (CPO) a reality. As the demands of data centers increase, so too do the demands on scale-up and scale-out connectivity. With AI accelerators now demanding extremely fast signalling speeds, CPO puts optical engines next to the processor or ASIC in order to shorten electrical paths, increasing data rates, shortening the electrical path, and consuming less power.
We dive deep into TSMC's COUPE roadmaps, which extend to 2030, and to a blistering lane speed of 400 Gb/s, Intel's CPUs with OCI chiplets, Samsung Foundry's path to building a CPO turnkey, and GlobalFoundries' vendor-agnostic OCI-MSA CPO platform.
That's not all we had on the roadmaps front this week, as we've taken a deeper look at China's chipmaking tool roadmaps, hot on the heels of the country announcing it will build DUV immersion lithography machines capable of producing 7nm chips by 2030. The more difficult equation is building a domestic EUV machine, which demands a robust supply chain of the right tooling and equipment, with over 3,000 workers reported to be working on what's now dubbed China's "Manhattan Project."
The country still relies on ASML's DUV lithography machines for chipmaking, as modern systems are subject to export controls, which is why Huawei, the creator of the Ascend series of AI accelerators, is keenly interested in getting the project off the ground.
But China has more on its mind than merely producing the machines; it also wants to spin up its DRAM output via CXMT, which is planning to expand to a brand-new fab to boost memory output. This comes following consumer brands and computer makers like Dell, Lenovo, and more. But it's no simple task, as we explore how the MATCH Act could impact CXMT's ability to produce DRAM modules on more advanced nodes.
There are also concerns around expanding wafer capacities and procuring the tools required for such an expansion, which targets 30% of market share by 2030.
On the memory front, Samsung has also debuted three brand-new memory technologies, zHBM, zNAND-O, and BV-NAND, which each target different markets and are all built upon advanced wafer bonding techniques. zHBM is expected to enable 8x the performance of HBM5, while zNAND-O,. which would allow the company to put four or eight stacks of NAND devices on top of logic dies. Meanwhile, BV-NAND represents Samsung's 10th-generation V-NAND and is the closest of the three announcements to commercialization.
You can read this lengthy technical breakdown of Samsung's announcements for free, even if you're not a Tom's Hardware Premium subscriber.
Is the AI tokenmaxxing party back on? With the release of the modestly priced Kimi K3 and DeepSeek V4 Flash-0731 over recent weeks, the emergence of competitive, cheap Chinese AI models has now forced companies like OpenAI, which launched GPT 5.6 Luna back in June, to cut prices by a staggering 80% in the wake of the competitive open-weight Chinese models. And OpenAI isn't the only company trying to offer more value to users. Anthropic replaced Opus 4.8 with 5.0, and Google also came out with the affordable Gemini 3.6 Flash and Gemini 3.5 Flash-Lite models, too.
So, where does that leave the AI industry? Western frontier labs must keep pace with the competition on offer overseas, and the intensifying competition is slimming down margins for what we assume to be already subsidized token costs.
Within the world of artificial intelligence, other stresses are looming for ChatGPT-maker OpenAI. The company is heading to court with tech titan Apple over claims that OpenAI stole trade secrets from Apple. The claim comes amidst OpenAI's development of dedicated AI hardware. OpenAI says it didn't want Apple's trade secrets, and that the Cupertino company was simply getting things wrong. Apple, however, alleges that 13 of its former employees passed along the aforementioned trade secrets, including documents sharing details of unannounced products and screenshots of sensitive materials.
We explore how the lawsuit is developing in this rather unusual offshoot, which centers around products that have yet to see the light of day.
That wraps up most of the major pieces of content that we published this week on Tom's Hardware Premium, with the bonus of being able to access our deep dive into Samsung's new announcements without a subscription.
For all of the other articles in this list, and to use our Bench tool, you can sign up to Tom's Hardware Premium today to read more. We'll be back next week with another roundup to keep you up to date.
Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.View Deal
The Beelink SER10 Max might look like a standard Mac Mini-style mini PC, but this unit is fairly unique when compared to many of its other Mini PC compatriots – it comes dual-booted with both Windows 11 and Ubuntu, the latter of which also comes with OpenClaw and a lightweight local AI model pre-installed on the drive. Sporting AMD’s Ryzen AI 9 HX 470, a light refresh that boosts performance over its predecessor by 100Hz and AI TOPS to 55 over 50, is the curious configuration a simple party trick, or is the $1,649 mini PC doing something actually useful?
Outfitted in a vibrant red, the PC comes ready to dual-boot between Windows 11 and Ubuntu with the additional boon of OpenClaw having been pre-installed on the system alongside a local AI model – Qwen 3.5-9B-Q4_K_M – on the Ubuntu install, meaning that setting the SER10 Max up for AI usage should be fairly straightforward. It’s important to note here that, despite the branding and usefulness of the setup, the HX 470 is hamstrung by a maximum memory bandwidth of 89.6 GB/s, a far cry from the Strix Halo’s 256 GB/s, meaning that local AI performance will be somewhat limited.
Design of the Beelink SER10 Max
(Image credit: Tom's Hardware)
Beelink has taken a few notes from Apple’s playbook for the design of the SER10 Max. While the underside and rear of the chassis are both made from plastic, the rest of the shell is made from high-quality machined aluminum. Our unit comes in with a red anodized aluminum finish, which looks fantastic, though it might not be to everyone’s taste. The red finish is specifically for units that come with the “OpenClaw” feature pre-installed. For everyone else, there’s a silver finish, which makes the unit look even more Mac Mini-inspired.
One thing to note about the SER10 Maxis is that, unlike some other mini PC’s, the power supply is external, meaning that you’ll have to find a place for the power brick to live. Luckily, the unit we were shipped came with a fairly long cable. It’s a tight, well-made package sporting vapor chamber cooling and a single active fan that never gets too loud while under heavy loads, which is a rarity when dealing with PCs in this form factor.
Specifications
Processor
AMD Ryzen AI 9 HX 470
Memory
64GB (2x32GB DDR5-5600)
Graphics
AMD Radeon 890M (integrated)
Storage
2TB 2280 M.2 SSD
Networking
10Gbps Ethernet, Intel AX200 Wi-Fi 6, Bluetooth 5.2
Front Ports
USB 3.2 Type-A 10Gbps, USB-C 10GBps, 3.5 mm audio jack
Rear Ports
USB4 (Type-C), HDMI 2.1, DisplayPort 1.4, 10Gbps LAN, USB 2.0 Type-A, USB 3.2 Type-A
Power Supply
100-240V AC, Output 19V 5.26A
Operating System
Windows 11, Ubuntu
Dimensions
5.31 × 5.31 × 1.76 inches (134.9 x 134.9 x 44.7 mm)
Price as Configured
$1,649
Ports and Upgradeability on the Beelink SER10 Max
(Image credit: Tom's Hardware)
There’s some easy-access ports on the front, though I would have liked to have seen more Type-C ports over Type-A. The USB4 functionality might also come in handy for anyone looking to run an eGPU dock. On the back, 10Gbps Ethernet could make it a handy machine for running locally connected workstations for AI development (though on this machine, it's probably better for fast networking). There’s nothing special to write home about here, though the additional feature of auto-power on via LAN is incredibly welcome, cementing the way that this PC is specifically positioned as a satellite compute unit.
The SER10 Max can be quite easily opened up, once you get past the adhesives. There are four rubber feet at the bottom of the chassis, which are unfortunately glued to the heads of the four screws. These are quite strongly bonded, and when I removed one of the small rubber stoppers, it flew off my desk, and into oblivion, never to be found again. Once you’ve taken your handy spudger or guitar pick, all it takes is removing four Phillips head screws, and a tug of a rubber tag at the bottom of the unit to remove the plastic bottom panel. There, you’ll be met with a dust filter, which takes another two screws to access the components within.
Our unit came with two populated dual-channel DDR5 SODIMM slots, in addition to two NVMe drives (one for each slot, housing each OS), which are underneath a heatsink, which is partially taped to another part of the chassis. You can easily remove the two screws holding the SSD heatsinks in place and lift it up, revealing two populated M.2 2280 slots, each housing a Crucial 1TB drive. Beneath the one on the right is an additional M.2 2230 slot, which is shielded, housing the Intel AX200 Bluetooth and Wi Fi module. These core components are all very easily accessible, meaning that if you wanted to upgrade your storage or if anything goes wrong with your connectivity at some point, it’s all user-replaceable, which isn’t a given with this segment of small PCs.
Productivity Performance on the Beelink SER10 Max
The SER10 Max’s performance across productivity workloads squarely put it in the middle of the pack for our currently tested suite of mini PC benchmarks. That’s no bad thing – the system can handle everyday office and demanding CPU tasks thanks to its 12-core / 24-thread configuration, which shines in multi-threaded workloads. In everyday use, I was not wanting for any more power than what was already on offer here.
Kicking things off with single-threaded results, we see that the Beelink SER10 Max sits slightly ahead of the HX370-based Arctic Senza AI 370, though it loses out to the MSI Cubi AI+ 3MG NUC, the latter of which uses an Intel Core Ultra 386H. Both HX470 systems in our benchmarks were slightly edged out by the GMKtec EVO-T2, a Core Ultra X7 358H-based system. In Geekbench 6’s single-threaded results, we see that the system fares slightly better than our overall geomean ranking, leading at the top of the pack by a slim margin. Multi-threaded workloads also tell a similar story, with the Beelink SER10 Max sitting second in our list of benchmarks against other systems, but not far behind the Arctic Senza AI 370, which, in all fairness, is only a single point ahead.
In real-world tasks, such as video editing for Tom’s Hardware’s ‘Quick Takes’ using Capcut, I found that the Beelink SER10 Max performed admirably, loading and rendering video, cutting and rendering at a solid speed, so I wasn’t waiting around for effects to be rendered within the timeline. In the videos I edited on the Beelink SER10 Max, I didn’t feel as though I was waiting around for anything to be rendered, effects to be applied, nor was I wishing that I was editing on a more powerful system. However, editing using a “light” video editor like CapCut, against something more powerful like creating effects using After Effects and Premiere, are very different things. Throughout operation, we only heard the Beelink SER10 Max crank its single fan up to full tilt once, during a synthetic workload. Otherwise, the system was remarkably quiet throughout our testing.
Gaming and Graphics on the Beelink SER10 Max
The Beelink SER10 Max is equipped with AMD’s RDNA 3.5-based Radeon 890M GPU, which features 16 CUs at speeds of up to 3.1 GHz. This isn’t going to suddenly be able to run every game perfectly, as the device out of the box is configured to dedicate only 4GB of its memory pool to VRAM. Given that we have a lot of memory in the system, those looking to game may wish to extend that RAM pool further for peace of mind that they won’t run out of VRAM throughout. All of our tests were run with the 4GB VRAM pool, as was configured out of the box, meaning that you’ll likely find some performance gains should you tweak it to be slightly higher.
In Cyberpunk 2077’s “Steam Deck” configuration at 1080p, the SER10 Max offers playable performance at 1% lows of 42 FPS and an average of 51 FPS, respectively. On Cyberpunk 2077’s High setting with all upscalers turned off, we see 1% lows of 25 FPS and an average of 30 FPS. In Cyberpunk, the Beelink SER10 Max is trailed only by the Arctic Senza AI 370, which has a faster memory pool, and the GMKTec Evo T2’s Arc B390, which also has faster memory.
Tom's HardwareTom's Hardware
In Shadow of the Tomb Raider, the same pattern is echoed; faster memory is just as important for serving frames as the silicon within, though the Beelink SER10 Max achieves an average of 52 FPS and 1% low of 40 FPS. This isn’t going to become a AAA games machine, nor should you expect it to perform that way. Synthetic benchmarks confirm what our real-world testing tells us – the newer Gorgon Point silicon doesn’t make up for slower memory when compared to the Arctic Senza AI 370’s 32GB of soldered LPDDR5X-8000.
Tom's HardwareTom's Hardware
However, in smaller and simpler titles like Hollow Knight: Silksong, the SER10 Max managed to reach an average of 100 FPS at 4K with V-Sync off, Particle Effects set to Normal, and Blur Quality set to High. This is about as expected for a 2D game of this type, and aside from the odd hiccup when transitioning between areas, it ran extremely well. In Stardew Valley while tending to my crops, the SER10 Max at 4K maintained a steady 60 FPS throughout.
While those two are markedly lighter titles, I also played co-op climbing hit Peak on the system, where running things at a native 4K resolution came up against the reality of its default 4GB VRAM configuration with render scaling set to native, where the game struggled to reach a baseline of 30 FPS, with the rest of the game set to High. Punching all the settings, including render scaling to Medium, I managed to get things running at a steady average of around 70 FPS. So long as you keep your expectations in check regarding performance in heavier 3D titles, the SER10 Max is a performant “indie” machine. Just don’t expect to light the world on fire with all the latest bells and whistles, or run expect to run the newest titles at native 4K resolutions.
Dual Booting on the Beelink SER10 Max
Dual booting between Ubuntu and Windows 11 is one of this unit’s flagship features, isn’t quite as straightforward as you might be led to believe. Instead of being met with an option between the two upon booting the unit to switch between OS’s, you must instead switch the boot drives within the BIOS to get to your preferred OS. This isn’t a dealbreaker, but there are some more caveats to the feature that potential buyers should know about.
Ubuntu and Windows 11, even while running on different NVMe drives, don’t play well together unless you’ve set up Windows first. In particular, the networking chip wasn’t recognized by Ubuntu until I had booted up Windows 11, set up the device, and restarted the system to boot into Windows again, then switched to Ubuntu. No amount of driver installations or re-installations on Ubuntu managed to solve the issue on our end. That was the only real problem that we encountered when testing the Ubuntu installation on our review unit.
(Image credit: Tom's Hardware)
Secondly, the OpenClaw installation is remarkably simple to set up, with Beelink itself offering a setup guide for new users (like me) who had never used OpenClaw before. A well-documented setup guide, and 10 minutes later, I had my own local LLM running on the system, and communicating to me via Telegram on my phone. It’s worth mentioning that Beelink also offers a pre-installed LLM for OpenClaw usage on the device, in this case, Qwen 3.5-9B-Q4_K_M.
When querying the model in the llama.cpp front-end, we found that the model ran at 11.4 TPS, which is quite slow. A 1,350-token query took around two minutes in total to generate, which is a fairly slow speed for those looking for light, fast responses. Getting OpenClaw to learn new skills is a crucial part of having a model running on your phone. Without it, the model will just occasionally lie to you. That’s not the PC’s fault, but a byproduct of running a 9B model locally. During the setup of OpenClaw, you can also install other LLMs that fit into the system’s memory, such as Google’s Gemma 4 model or other lightweight LLMs. However, given that this system cannot quite manage to fit larger, more complex LLMs locally, you also have the option to use an API key for your provider of choice, which removes some of the load and opens the door to running more agents concurrently on the system.
The reality is that for Local AI and AI development, you’d be more suited to spending more on an AMD Strix Halo or Nvidia DGX Spark-based system, as those offer much more performant architectures and higher memory bandwidth for running larger, heavier local models. However, for those looking to simply dip their feet into the Local AI waters, the SER10 Max is capable of running some of those tasks, but you’ll be looking to upgrade your hardware sooner rather than later if this is the main reason behind your purchase.
Software and Warranty on the Beelink SER10
The SER10 Max comes with a delightfully lightweight and bloat-free Windows 11 installation, shipped with Windows 11 Pro 24H2, meaning that once you get the unit, you’ll likely want to upgrade it to 25H2 if yours hasn't already. Oddly enough, it took a few attempts to successfully install it, after several rounds of failed updates. Soon after, we were up and running with no issues, but Beelink should really update its Windows installation image to 25H2 to smooth onboarding for new users. Over on the Ubuntu side, you’re simply looking at having all the files for OpenClaw pre-installed. This is a pretty refreshing take, as the system is not filled with bloatware. Once you’ve installed all of your drivers on the system, then things are fairly nimble and lightweight.
Beelink offers a three-year warranty on its website, which covers manufacturing defects or if the product does not work as advertised. While you can go straight to Beelink’s website and purchase the system, many models of the SER10 Max are also available via Amazon.
Beelink SER10 Max Configurations
Beelink offers the SER10 Max in a multitude of flavors and configurations. The base model offers Windows 11 Pro, in 32GB/1TB and 64GB/1TB flavors with a silver anodized aluminum finish, priced at $1.299 and $1,599, respectively. The “OpenClaw” models ship with Ubuntu and come in the red colorway and can be specced slightly higher. The 32GB / 1TB will cost you $40 more than the Windows 11-based equivalent, while the 64GB / 1TB OpenClaw config retains pricing parity to its Windows 11-based brethren.
The OpenClaw configurations also ship with more DDR5-5600 RAM and 2TB of storage. The configuration we reviewed, the 64GB / 2TB OpenClaw model, will set you back $1,799, and is the only model that ships dual-booted. You can also equip yourself with a 96GB / 2TB variant, which tops out at $2,199.
Shopping around for other Gorgon Point Mini PC’s of this type, Geekcom’s A9 Max is $100 more expensive for the base model, whereas the MINISFORUM AI X1 Pro-470 in a 64GB/1TB variant costs $1,639, whereas Beelink’s SER10 model with the same RAM and storage capacities is slightly cheaper at $1,599.
Bottom Line
The Beelink SER10 Max’s appeal is curious. On one hand, you have a well-performing desktop PC that can churn through most productivity and performance tasks with ease, and is even well-suited for some light gaming. For the past week and change, it’s even acted as a suitable replacement for my desktop gaming PC in a pinch, and I’ve not been left wanting on the performance front in my day-to-day usage. The biggest weakness of the SER10 Max is in its fairly limited memory bandwidth, capped at 89.6 GB/s. We’ve seen this limitation crop up in some gaming workloads, where previous-generation silicon with faster RAM beat the SER10 Max’s HX470 out. We’ve also seen the unit butt up against this limitation when serving tokens for local AI models, as the system must communicate between the model weights stored in the RAM and push them through the APU for every single token generated.
Where the confusion comes is in the OpenClaw-based branding of the unit, as a result. The Ubuntu dual-boot is handy, but far from a difficult task to perform for someone familiar with the platform. For prospective AI developers, there is merit in being able to run a smaller model locally at lower token speeds, while also leveraging a more powerful cloud model. But you would need to take a hybrid approach. Don’t expect to suddenly abandon your Claude subscription for a model that this the SER10 Max can run – you’ll only set yourself up for disappointment. This makes the OpenClaw branding come across more like a marketing gimmick, rather than an actual day-in-day-out use case, unless you’re dedicated enough to set up a hybrid local and cloud AI setup, where you’re passing off smaller tasks to a slower locally-run model.
This makes the particular configuration that we’ve reviewed niche in its overall utility for AI enthusiasts. You have to go in understanding all of the limitations of the hardware before even considering purchasing it. For some, the configuration on offer here will suit just fine; for others, particularly those interested in running powerful local AI models – you should instead look toward systems with faster memory bandwidth, higher memory capacities, and speeds. Luckily, it’s not a dedicated AI box, and the SER10 Max is a quiet, performant desktop computer that’ll suit most everyday tasks incredibly well.
Unless you’ve been living under a rock, OpenClaw has dominated headlines, both good and bad, for much of early 2026. Developed by Peter Steinberger, the tool is an engine that spins up an AI agent that can autonomously act on your behalf, going so far as having the ability to run files, browse the web, and much more. Using a system named “Skills,” you can even teach your AI assistant to perform new tasks, with more integrations popping up daily. But how useful is it for the average person? I took it upon myself to answer that question by using the relatively humble Beelink SER10 MAX mini PC, which comes pre-installed with OpenClaw, to find out.
To kick things off, when setting up your OpenClaw installation, there’s a fairly large decision one has to make: Do you want to rely on Cloud resources and more powerful AI models, or run something locally? Beelink’s SER10 MAX ships with Qwen-3.5 9B, which is a relatively older and more outdated AI model. Since I want to keep things fairly simple, I opted for the local AI route first. To run larger models, you’ll need a lot of memory, so I first tweaked the humble Mini PC’s video memory up to 48GB, which should allow us to keep a larger, more complex model in memory. It also leaves us 16GB of system memory to play around with, which should be more than enough to run the terminal and ensure that everything else works as intended.
Selecting the ideal local AI model
Having 48GB of available video memory should allow us to run a fairly powerful AI model on the system. However, the downside of running a larger model is that token speeds are likely to be slightly lower than expected. However, for running the super-smart AI that does things for us locally, we want as much intelligence as we can get. For this exercise, I chose Google Gemma 4 31B (UD-Q8_K_XL), a near-lossless quantization, somewhat ambitiously, as I will learn shortly.
After downloading the model and running it in llama.cpp, we managed to attain 2.34 tok/s. On average, everyday queries took 116 tokens to generate, at 2.34 tok/s. That’s still too slow for fast everyday use. So, I took a deep breath and conceded that the humble Ryzen AI 9 HX 470 didn’t have fast enough memory or memory bandwidth to run such a large model at acceptable token speeds. Even if I had dropped the quantization to 4-bit, we’re still looking at the theoretical maximum of around 5 tok/s for that model in particular. If you had a faster machine with rapid RAM speeds, such as a Strix Halo system like the Framework Desktop, it might be more workable, but for a lower-end piece of silicon with relatively humble DDR5-5600 speeds, you’ll just have to accept a slightly more neutered model.
So, I eventually conceded that the smaller Gemma 12B (Q4_K_M) was a much more sensible choice for a device of this caliber. After loading things up into llama.cpp, we managed to get a much more sensible 10.64 tok/s on a general knowledge query: “What is Tom’s Hardware?” Now that I have a little piece of talking electrified sand on my desk, it’s time to configure OpenClaw.
Hatching HammerClaw
(Image credit: OpenClaw)
The device I am using, the Beelink SER10 MAX, comes with OpenClaw pre-installed. The only real dependency it has is llama.cpp, which we configured earlier while testing which AI model to use. Since the llama.cpp port is open, OpenClaw leverages that to talk to the AI model, with all of its additional fanciness included. The OpenClaw installer is fairly straightforward in getting things up and running, including setting up a Telegram channel to communicate with our AI model remotely and configuring a gateway, so we can configure things without relying on Ubuntu’s terminal commands.
Within the installer, we start to define our new AI assistant: It asks what its name and identity are, some basic details about the user, as well as what principles it should uphold, in a very extravagant file named SOUL.md. Remember, our talking sand isn’t alive, so it’s all quite dramatic. Generating a SOUL.md file takes a while for our humble local AI model, which I’ve named HammerClaw. But can it do anything useful for me to justify its nascent AI existence? Right now, it’s taken five minutes to think about exactly what it is and what it’s doing.
After a little while, our little HammerClaw “hatches,” asking what its purpose is, who I am, and how it should talk. Personally, I don’t like it when AI models are verbose, so it’s straight and to the point, and should never, ever lie to me. When AI models can scale to rather humble devices like this one, the smaller, less-intelligent models can be error-prone. With our little local AI agent alive and kicking, it’s time for it to automate a task for us; it couldn't be that difficult… right?
Stumbling blocks
HammerClaw quickly wakes up, and I offer it a task: to gather ten news articles from trusted outlets and different parts of the day, ensuring freshness, with a small digest of what’s happened. Since most of my work on Tom’s Hardware Premium is centered around chipmaking and data centers, I want it to focus on those topics. HammerClaw then quickly takes the task and starts working out how to pull it off. It’ll use its built-in cron tools and felo-search to pull stories from the internet.
Now, here’s where things go bad for poor HammerClaw. It then begins to simulate the action, instead of actually performing it, despite saying that it had set up the cron jobs and skills required for the automated scheduling. Even worse, it hallucinated a list of links that went absolutely nowhere. After pointing the error out, it gets apologetic and investigates why things went wrong. As it turns out, some additional parts need to be configured, which it tried to do and failed once again. Agentic Tool use is now a specific benchmark, but when asking Gemma 4 12B to set up a multi-step task like this, it simply couldn’t manage with the conversational tone of my prompts.
OpenClawOpenClawOpenClaw
It’s at this point that I asked HammerClaw to give itself a grade, to which it offered itself a B- on accuracy for hallucinating and making up news stories. Now, I don’t want to say that all OpenClaw AI agents would do this, as we are running a relatively light local model. I would expect that larger local models would be able to identify what they need to do much more efficiently due to having a significantly higher model parameter count. With that in mind, I wondered if another AI model could help HammerClaw along a little bit with this task. And so, I went onto my OpenRouter account and opened a chat with the big, beefy 2.8 Trillion Parameter Kimi K3.
Kimi K3 saves the day
Comparing a cloud-based frontier model like Kimi K3 and Gemma 4 12B just isn’t fair. One takes up terabytes of RAM to run, while Gemma fits inside a Mini PC that lives on my desk.
Instead of using Kimi K3 to run the AI itself, I tasked it with actually helping me set up the job that HammerClaw seemingly didn’t have the skills to pull off. This hybrid workflow – of using a local LLM in tandem with a more powerful one in the cloud- is a common setup for many AI enthusiasts. After about a dollar in tokens, it sent me a list of OpenClaw commands, skills, and instructions, after reading the current documentation for OpenClaw CLI to ensure it got everything right. It was flawless. I followed the instructions Kimi K3 gave me and entered them into an Ubuntu Terminal, where it successfully created a new skill for HammerClaw named ‘News-Intel,’ instructed me on how to enable the web-search functions, and set up the Cron jobs for the automated sends. Bearing in mind that I had never used OpenClaw before, it was all surprisingly smooth, even if our local model couldn’t do all of these tasks itself.
(Image credit: OpenClaw)
With everything set up, the buck is then passed back to our much humbler Gemma 4 12B model-powered HammerClaw to execute the rest – after all, this is supposed to be a test for how Local AI models function. I executed the command for a manual run while checking the operational logs, where it was successfully calling all of the tools, and thought, against all odds, HammerClaw might actually be able to do it. A few minutes later, I received a Telegram message. HammerClaw had managed to locally execute the task and send me a digest of ten news stories.
(Image credit: OpenClaw)
Of all of the things to automate, this is likely one of the simplest examples of how someone can use OpenClaw. While simple, it’ll also save me a bit of time every day staring at an RSS feed and looking for stories myself. But, it’s quite a distance away from the “speak, and it’ll do whatever you want it to!” promise that drew so many into a frenzy earlier this year.
Is it worth it for the average person?
If all you heard about OpenClaw is that it’s a magical AI agent that can do anything, as I’ve learned, it’s not quite the truth. Unless you’re well-versed in several elements, like understanding model choices and getting your head around what models perform well for tool-calling. Running a humble local setup might be fun, or interesting to tinker around with, but the true power for Local AI developers and tinkerers lies with the obvious: More power to run bigger, complex models, and more agents running tasks consecutively. In fact, we’ve taken a look at how these workflows can be used in practice with a mixture of Local and Cloud AI models for Tom’s Hardware Premium.
The issue here is that for our local model, this simple task – of running and sending us 10 news stories- could not set itself up, and that’s using hardware that already costs north of $1,500. As our resident local AI expert and GPU guru Jeff Kampman has recently tested, for those serious about AI who want real power without relying on the cloud entirely, you might want to save up your pennies to run stronger, faster local models, either using dedicated GPU-accelerated setups, or dedicated boxes such as the DGX Spark, or a cluster of Dell Pro Max GB10s, both of which will cost you north of $5,000. You’d hope that the models capable of running on that hardware wouldn’t fumble the setup of a relatively simple Cron job.
The real question is, will having a local AI inference box meaningfully change how you work, or the work you do, to pay for itself? For many, that’s the lingering question that many are asking themselves. For now, HammerClaw is sending me more articles every few hours, a task that can be performed by simple scripting. But the manual “sift” is being handled by an LLM. As neat as it is, I wouldn’t pay $1,500 for the privilege. Luckily, it’s not merely a box made for AI inference; there’s a whole computer attached.
We take a brief look at FEX, the translation layer that allows PC games to run on ARM64 devices, such as Android Tablets. While the results are promising, it still has a long way to go.
Enter your build to the Tom's Hardware Rig Rundown for a chance of winning a $100 / £75 gift card, and have your setup reviewed by our team of experts.
 登录